12359 stories
·
36 followers

The Mathocalypse

2 Shares

Updates (Oct. 9): To address some questions that keep coming up…

No, I’m not aware of any direct practical implications of any of these results. I certainly don’t expect the O(n log0.9999999999999 n)-time Fourier Transform algorithm to get practically deployed anytime soon! But anyone who harps on this, simply doesn’t understand what mathematical progress looks like, or how it eventually pulls the rest of science and technology and human civilization with it. If and when the relevant human mathematicians understood the clever new ideas in all 372 of these papers, I have no doubt that they’d be able to use the ideas to do all sorts of new things, and that some of those things would have practical value. That’s yet another reason to try to keep human understanding at the center of our enterprise—unless, of course, you’re happy to outsource the task of understanding and applying the ideas to AI models as well.

Meanwhile, something calling itself the Association for Human Mathematics put out a statement condemning OpenAI for its release. The statement included a sentence that’s since been widely mocked on social media: “Mathematicians did not ask for this work to be done.” (Imagine G. H. Hardy saying to Ramanujan, “who asked you to prove all these bizarre new identities?”)

If it wasn’t clear, the members of AHM speak for themselves, not for the math community as a whole. For my part, I think the math and CS theory communities should absolutely hold the AI companies’ feet to the fire to behave better, both within our little domains, and (much more consequentially) in pacing AI progress, figuring out alignment, and preventing a catastrophe for our whole civilization. So I’m glad that our communities have increasingly been doing that, and I hope to have played a tiny part.

At the same time, I regard the position “no one should spoil our fun by solving our open math problems using AI models” to be totally untenable. It offers no argument for why refraining would be in the broader public interest—as opposed to various mathematicians’ narrow career interests. It violates the core principle that math problems are there for absolutely anyone (yes, even a hated corporation) to try to solve. And of course, it’s not enforceable anyway, in a world where these capabilities will rapidly diffuse to anyone with a GPT or Claude subscription.

We will need to adapt to this new world.


… then they came for Navier–Stokes and I said nothing because I never worked on Navier–Stokes. But when they came for RL vs. L I realized that things are serious

–friend-of-the-blog Omer Reingold (shared with permission)


Last night my 9-year-old son was taunting my wife, complexity theorist Dana Moshkovitz, as follows: “mommy, I heard you got cooked! I heard that a robot solved the math problem you worked on for your whole career! OOF!”

While my son was being a brat, he also wasn’t wrong. Whether you’re thrilled, depressed, angry, or whatever else about it, yesterday was surely one of the biggest days in mathematical history. And yes, among the 372 huge results released yesterday by OpenAI, on the recommendation of its advisory group of Timothy Gowers, Edward Witten, and other distinguished mathematicians, was a proof of Subhash Khot’s Unique Games Conjecture (UGC), a statement that my wife has worked toward proving for the entire time I’ve known her. (The UGC implies that a whole slew of optimization problems really are NP-hard, even if you just want an approximation that’s slightly better than what you get from semidefinite programming relaxation, which is one of our main tools.)

Or at least, we’re pretty sure that it’s a proof! There’s a Lean certificate, as there are for some of the other 372 breakthrough results (not all of them). But it also appears that no human has understood just about any of these proofs yet; the race to do so has just started. If you want an on-the-ground sense of what that race is going to be like, here’s some of what Dana texted me last night:

It feels like something written by someone who’s on psychedelics. So much unclear and doesn’t make sense. Lots of name dropping of previous work without discussing why it can be used despite impossibility results

Basically the paper is so horribly written that it’s impossible to read it without AI help

I asked Astra for reasonable completeness and soundness claims of the noise gadget and it gave them by combining claims from all over the paper

They also have direct optimal NP hardness of approximation proofs for the main applications of the UGC (Max Cut and all CSP) that bypass the UGC.

The UGC proof invents a completely new bizarre code with a noise test. It’s some crazy recursive construction.

It’s not the long code, not the short code – some alien craziness

I still think that there maybe is a proof that uses the half space code (which is natural)

The citations are often irrelevant and confusing

A possible future is a math world that’s heavenly if you have vision/creative ideas that AI could help check and implement.

And of course there’s a lot for us to learn from the aliens

If you’re wondering what emotions Dana is feeling—well, probably all of them! Even while a central career aspiration has fallen to a robot, there are at least two mitigating factors for her. First, she can feel vindicated that the UGC was true after all, something she never doubted even while many of her colleagues did! Second, all of us in math and theoretical computer science and mathematical physics, at least those who cared about solving crisply-stated problems, are now in the same boat.


Besides the Unique Games Conjecture, here’s a small sampling of the treasures from Aladdin’s cave that I’ll probably be paying the most attention to over the coming weeks:

Any of the above, alone, could easily have been “result of the year” in some area (and in some cases, like Unique Games and L=BPL, in all of CS theory). And there’s a lot that I’ve left out—feel free to share in the comments whatever is making your eyes bug out! There are equally astounding wonders in number theory, combinatorics, algebraic geometry, analysis, and pretty much every other area of math, most of which I’ll never understand, although I’ll note that it includes partial progress toward the Riemann hypothesis and the Hodge Conjecture and the Birch-Swinnerton-Dyer Conjecture (i.e., the majority of the remaining Millennium Problems).

We can take solace in what’s missing from the list. P≠NP isn’t there, nor even P=BPP or NEXP⊄P/poly, and surely not for lack of trying. Apparently the greatest open problems of theoretical computer science are indeed pretty hard!


Oh, lest I forget: one day before the OpenAI dump, meaning Monday evening, Virginia Williams and Josh Alman posted an arXiv preprint that solves the 3SUM problem in O(n1.9992) time, and the All-Pairs Shortest Paths problem in O(n2.9995) time, refuting half-century-old conjectures that the correct answers were n2-o(1) and n3-o(1) respectively. In this case, it wasn’t an OpenAI model that supplied the crucial idea; it was an Anthropic one! But Anthropic then took a different approach from OpenAI: rather than post the undigested solutions to the world, it gave Virginia and Josh the opportunity to write and announce a digested version in exchange for compensation.

These have emerged as the two main models for communicating AI math breakthroughs, and they both have strengths and weaknesses. The “OpenAI model” sets up a crazy race among humans to digest and explain a messy AI proof (work that could easily be some combination of thankless, barely-credited, competitive, and unfun), while the “Anthropic model” puts a private company in the position of picking and choosing which human mathematicians get to be the emissaries of the AI. Dunno, what do you guys think?


For those who are wondering: apparently, the AI model that produced all these wonders was not bespoke contraption of 10,000 agents burning millions of dollars worth of compute, as was used for example to construct a finite-time blowup for the Navier-Stokes equations. Instead, it was simply the latest internal OpenAI model—one that might be released to paying ChatGPT customers within the next couple of months, depending on the recommendations of OpenAI’s safety board! (My 9-year-old son: “Oh they definitely shouldn’t release that. If it could solve all those math problems, it can’t possibly be safe.”) Apparently they used about 3 hours of GPT-Pro level compute on average per problem solved.

Also, if you were wondering: apparently they tried the model on about 8,000 problems. So, right now it “merely” solves ~5% of the longstanding open mathematical problems that it’s asked about, the problems that whole communities have spent years on, after a single 3-hour attempt on them.


I’ve been glad to see the CS theory community rising to the occasion. At the Simons Institute in Berkeley, here at UT Austin, and elsewhere, I’ve hearing stories of researchers rushing to pore over the manuscripts and make sense of them and explain them—because what else do we do? How else do we continue the craft to which we’ve devoted much of our lives?

If you want some sense of what things feel like now in math, imagine a hunter-gatherer who’s spent his entire life learning to survive deep in an unforgiving rainforest, then a giant resort hotel springs up right next to him with a helipad and heated pools and AirBnBs, and without missing a beat, the hunter-gatherer says: “alright fine, so now my new job is to run wilderness retreats for the tourists, or something.”

In Quanta magazine, Jordana Cepelewitz attempted a different metaphor:

It’s as if you were teleported to the peak of a tall mountain. Surrounded by fog, you have no idea where you are, or what’s around you. You do not know how your mountain connects to others, and you have no equipment to help you explore, no way to help someone else join you. If you had climbed the mountain yourself, you would have experienced how the human body adapts to altitude and changes in oxygen levels. You might have had to invent tools to navigate, to climb steep cliffs, or to make a shelter. You might have encountered a fellow explorer, gotten lost together in a hidden valley, and found a plant that could be turned into a life-saving medicine.

Instead you’re perched on the peak but in the dark, while the maker of the teleportation machine tells you that it can explore the wilderness better than any human.

For any one of these mountains, if we care enough, I feel optimistic that we can do as we always have: clear the fog and figure out the path, except now using the teleportation machine to help guide us. The bigger challenge will be to nurture a community that still cares about the heroic adventure of finding the paths up these mountains in the world with the machine. (Oh, and I think one place where the metaphor breaks is that we still do have each other, as much as we ever did before!)


Experience has shown that, even now, there will still be people explaining in patronizing tones why none of this is real and none of it counts. If such people were capable of being impressed by anything that happens in the empirical world, of updating on anything, they would’ve already been impressed and already updated several years ago, long before things had reached the point of an actual Mathocalypse.

So, they’ll say, maybe the alleged solutions are not solutions at all, but just “AI slop.” Or maybe none of the 372 well-known open problems that were solved were real math problems, they were all just glorified contest puzzles and trivialities. (After all, there’s still no Riemann Hypothesis!) Or maybe the entire 4000-year-old discipline of mathematics needs to be jettisoned: turns out that it was all just puzzle-solving and trivialities; all that’s different is that now the triviality stands unmasked. In any case, what really matters is that the true inner sanctum of human creativity hasn’t been breached and probably never will be, and also, that Sam Altman and Dario Amodei are contemptible little nerds.

If you’re still a proponent of that doomed worldview, still aboard the sinking ship, I encourage you in the strongest possible terms to read yesterday’s other great contribution to AI discourse, besides the OpenAI Mathocalypse dump: namely, Scott Alexander’s open letter to Steven Pinker. I feel some responsibility for this, as the person who first introduced Steven Pinker to the existence of the rationalist community, and who also first introduced Steven Pinker and Scott Alexander to one another (they had both been fans of each other’s writing). And now Scott is challenging Steve to a literal duel, with guns!

For whatever it’s worth: Steve is a lifelong intellectual hero of mine, just as he is for Scott, and I also have to privilege of calling Steve my friend. But I found Scott’s post to be one of the most devastating rejoinders to anything that I’ve ever read. And I thought Scott’s conclusion was exactly right: when it comes to AI risk, Steve’s great challenge is now to accept and start using a more “Pinkerite” epistemology.


Last night, while I should’ve been poring over some of OpenAI’s hundreds of papers and/or writing this post, I decided to spend some time with my kids instead. They wanted a movie night, so I suggested something they’d never seen before (and that I hadn’t seen for decades), and that seemed chock-full of no-nonsense, practical guidance for the world in which they’re going to grow up: Terminator 2.


Update: As several people have pointed out, cryptography is a subfield that’s extremely conspicuous by its absence from OpenAI’s list of 376 papers! But my sources tell me that the AI companies have now started, gingerly and discreetly, investigating whether their latest internal models can break important cryptographic protocols and primitives. If they can, then it would certainly be nice to get ahead of things before the rest of the world figures out the same.

Another Update: The statement put out the Advisory Group on Mathematics and Artificial Intelligence is very carefully phrased, neither endorsing nor condemning what OpenAI did, and is worth a read:

As announced a few weeks ago, OpenAI has released a large collection of mathematical results generated by an internal model, reporting solutions to hundreds of open questions. This is an important event for mathematics, with consequences both for mathematics and for the mathematical community that extend far beyond the individual results.

AGMAI’s advisory role should not be interpreted as a judgment of the impact of these results or an endorsement of the process by which OpenAI obtained them. We do not speak on behalf of the entire mathematical community, and only the mathematical community can undertake the assessment that is needed. 

Making this work public is a first step. This release is the beginning, not the completion, of the process of human understanding and the incorporation of the work into mathematical knowledge. At the same time, the future of mathematical research cannot consist only of understanding results produced by AI labs. Mathematicians must be able to formulate their own questions, develop their own approaches, and explore directions that have not been selected as examples of an AI system’s capabilities. Equitable access to powerful research tools and adequate computational resources are essential to that freedom.

We reaffirm our published recommendations on responsible release. We have discussed them with OpenAI and appreciate the company’s willingness to engage. While we consider these discussions constructive, it is ultimately up to the mathematical community to assess the extent to which our recommendations were followed successfully, and whether there are others we should suggest. We remain committed to engaging with any frontier AI lab on these questions and have already been in contact with several of them.

Read the whole story
denubis
16 hours ago
reply
Share this story
Delete

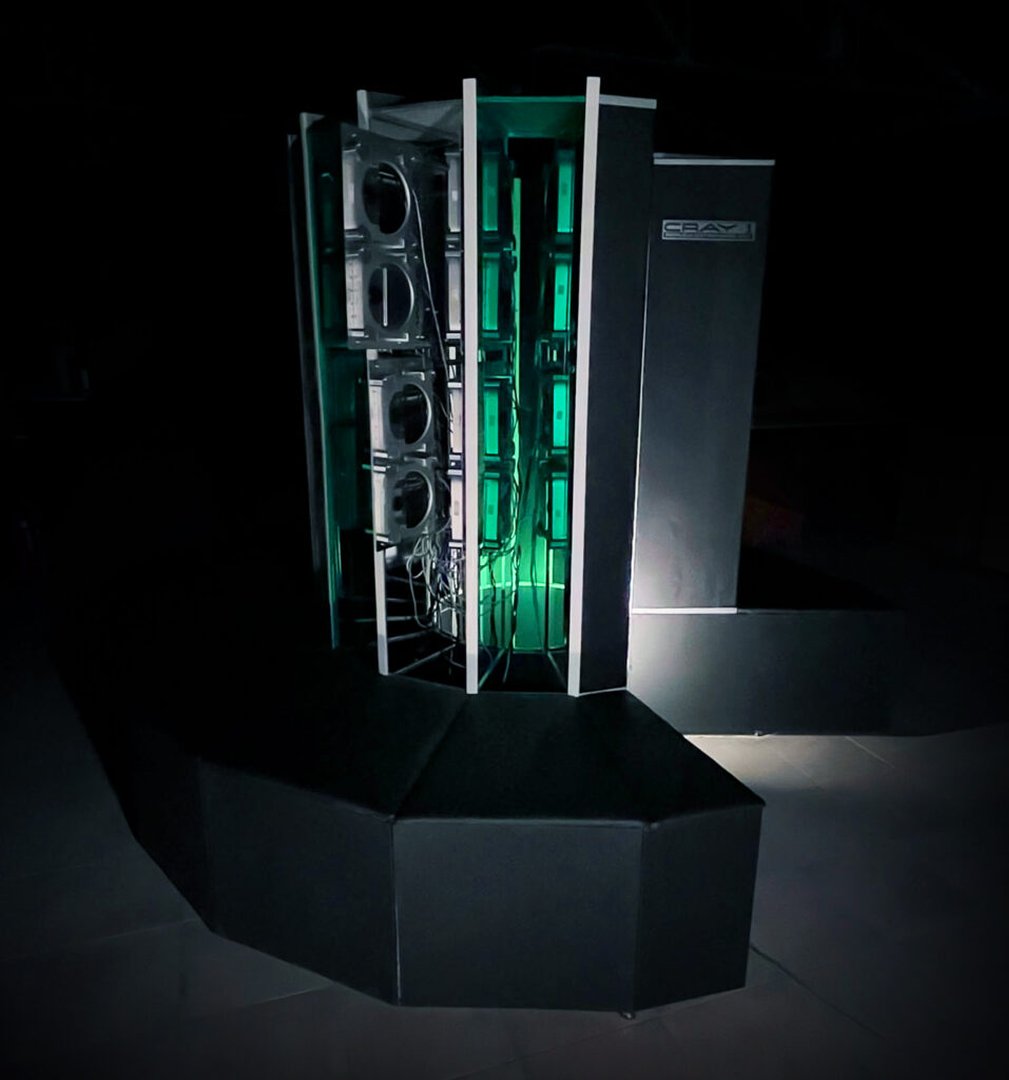
A Cray-1 supercomputer replica from 30 "obsolete" Mac Minis

1 Share

The Museo de Historia de la Computación in Spain has unveiled a 1:1 scale visual replica of the famous Cray-1 supercomputer from 1976. Instead of sourcing expensive, cutting-edge tech to run the system, the creative team powered the project with 30 2012-era Mac Minis. Developed over 18 months, the project serves as a 50th-anniversary tribute to the Cray-1 and Apple's founding.

Mac Minis from over a decade ago might not seem like the obvious first choice for building a cluster supercomputer, but when networked together, the developers can orchestrate the 64 active processing cores into a combined 1.3 teraflops of performance in their most recent tests. The museum reportedly achieved 1.5 teraflops previously using all 70 available cores, prior to one node going offline. Benchmarks were obtained using a custom matrix-multiplication Python script. Five PCs are quad-core i7s, and the remaining 25 are dual-core i5 models. Except for two units from 2014, the rest of the array dates to 2012.

The replica is a valuable tool for museum-goers to understand the shifts in computer architecture since 1976. The original Cray-1 used vector processing, applying a single instruction to multiple data elements simultaneously, whereas the replica distributes work across independent processors in a parallel cluster. The peak theoretical performance of the original Cray-1 was approximately 160 megaflops. What was originally a purpose-built research machine has been re-created with consumer hardware that's vastly more capable than the machine that inspired it.

Rather than opting for a more standard Linux distribution, the team found that macOS Mojave (10.14) met their project needs by harnessing macOS's built-in support for MPI (Message Passing Interface), the software layer that allows all the nodes in the cluster to pass tasks to one another.

Photograph of the museum's mac mini-powered Cray display The Cray-1 replica, complete with iconic padded bench seating. The only thing missing is Robert Redford and Ben Kingsley having a discussion on SECTEC Astronomy. Credit: Museo de Historia de la Computación Credit: Museo de Historia de la Computación
Guests at the Museo de Historia de la Computación can watch in real time as the system runs matrix algorithms, mapping the scale of system performance from a single core to the full suite running in parallel.

Stealth supercomputing

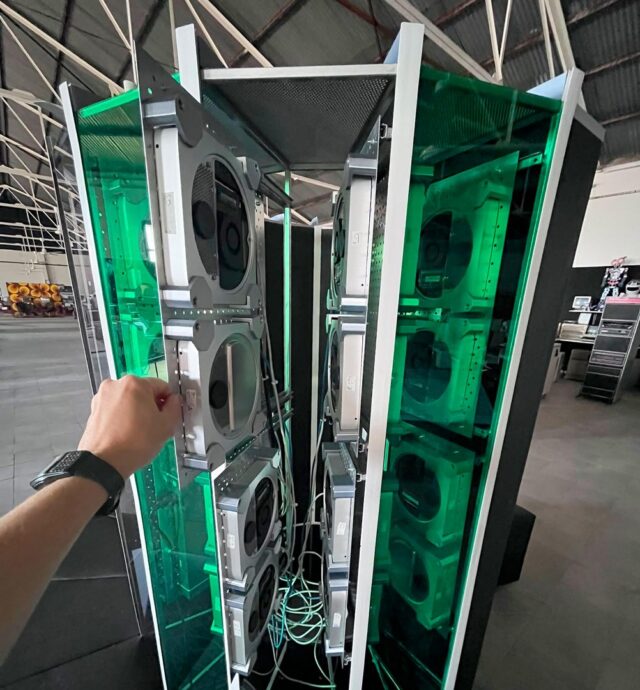
Combining 30 consumer PCs into an operational cluster wasn't the only engineering challenge the team faced. If you've ever stepped inside a server room, or, like me, foolishly installed one in your own basement, you know that fan cooling can be loud. The museum team used passive convection cooling via a steel rack chassis and aluminum tray mounts for each Mac Mini. Compared to the roaring thunder of a modern data center, this cluster is nearly inaudible.

Cray-1_Tower_Unit14 Macs are mounted vertically on aluminum racks in a steel chassis. Credit: Museo de Historia de la Computación
The secret to the near-silence comes from vertical mounting. The PCs' vertical orientation, combined with the steel chassis and aluminum trays, allows the tower to act as a natural thermal chimney. Hot air rises through the structure and out of the top grills without the need for added mechanical fans. According to the museum, the only noticeable noise inside the Cray-1 replica comes from two gigabit Ethernet switches at the base of the unit that register between 30–33 decibels, though the team plans to replace them with silent models. The fully assembled replica is said to make so little audible sound that you have to get right up next to the tower to be able to hear anything. While exact dB  measurements from inside the exhibit weren't available, each individual PC is stated to produce 12–15 dBA of noise at idle.

Mission control

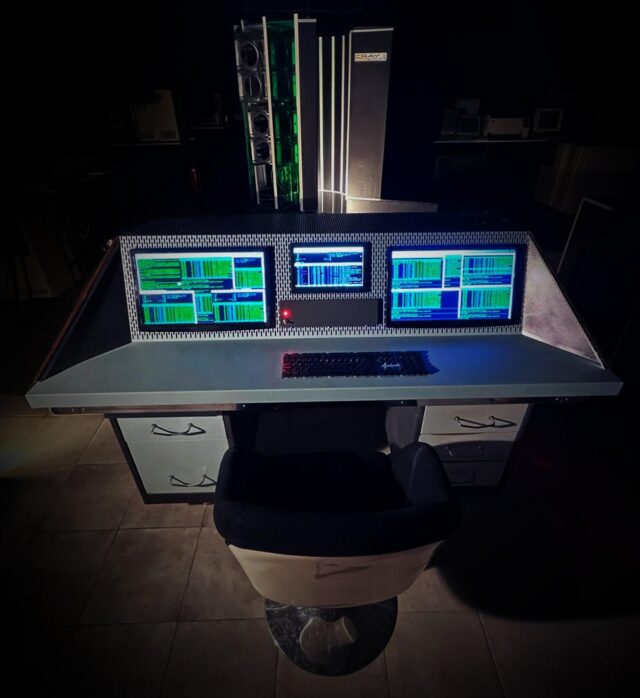
To manage this quiet giant, designers built a custom terminal that looks straight out of a Cold War control room. The team combined elements of the DEC VT05 and Processor Technology Sol-20 Terminal Computer designs of the 1970s, even incorporating an analog control panel, with future plans to add original lamps from an IBM System/3. One master Mac Mini resides in the terminal and serves to direct all the other cluster nodes.

Cray-1_Terminal_and_Tower_Background Classic design elements lend the Cray-1 control terminal some retro style. Credit: Museo de Historia de la Computación
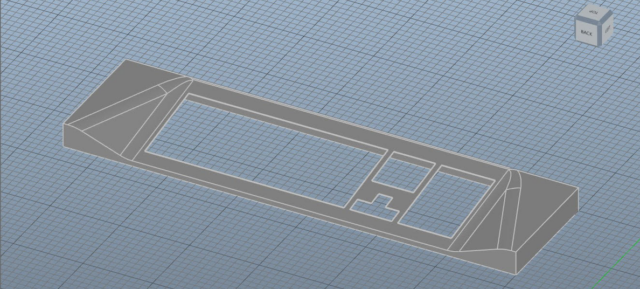
The original design had planned for the terminal to feature CRT monitors for added authenticity, but modern flat Samsung displays eliminated the connectivity headaches that come from attempting to bridge different technological eras. Future design plans will see 3.5- and 5.25-inch floppy drives mounted to the underside of the desk, and a 3D-printed shell will encase the keyboard to mimic the look of the classic HP 250 design.

A mockup in 3D printing software of a potential keyboard cover design. Mockup of the shell that will fit over the existing PowerMac G4 keyboard. Credit: Museo de Historia de la Computación
Targeting the TOP500

The Cray-1 team hopes to fill the currently empty second half of the tower through a crowdfunding campaign to secure 70–80 additional M4 Mac Minis. The goal: create a cluster capable of ranking on the TOP500 supercomputers list.

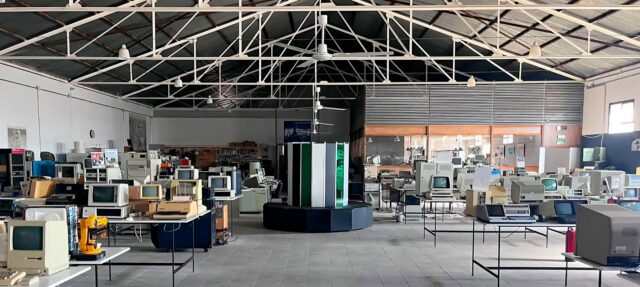
Cray-1_Replica_Bright_Room_PCs The Cray-1 replica among its classic computing peers. Credit: Museo de Historia de la Computación
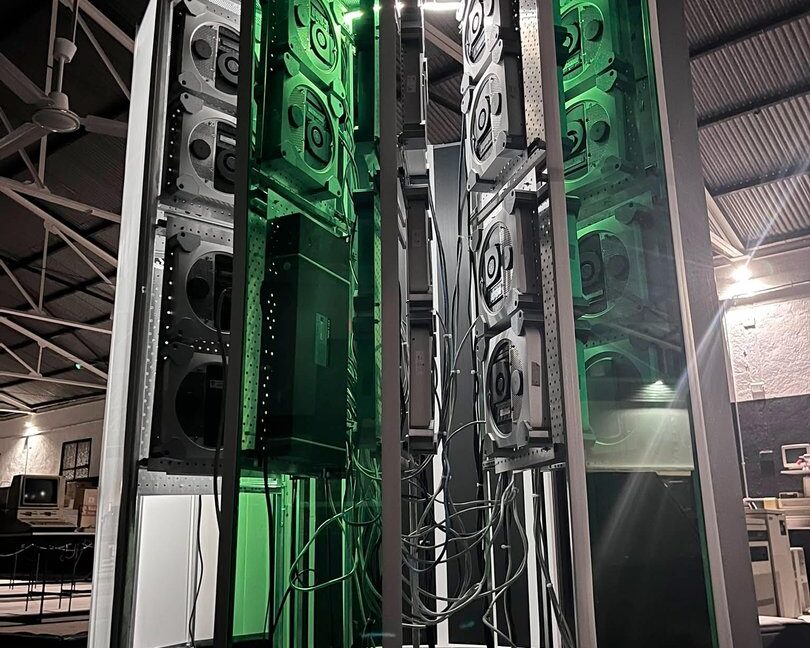
The replica is on permanent display in the museum, alongside two unused authentic Cray CX1 systems. The Museo de Historia de la Computación offers guided tours on Saturdays from 11:30 am to 2 pm. Additional project information can be found on the museum website.

Read full article

Comments


Read the whole story
denubis
19 hours ago
reply
Share this story
Delete

Muse, Meta's extraordinarily privileged AI assistant, has a serious 0-day

1 Share

Meta founder and CEO Mark Zuckerberg has gone to great lengths to hype the security of its new AI assistant Muse, claiming it is “built from the ground up for privacy and security.” A zero-day vulnerability that gives locally run apps and terminal commands complete control of the agent raises serious doubts. Further raising questions, Amazon on Sunday began blocking Muse from its site.

Meta introduced Muse a few weeks ago. The assistant “books appointments, fills out forms and handles customer service,” “proactively takes tasks off your plate,” and can “make purchases, generate images, create documents, and connect with your favorite apps and services.” The macOS app (curiously, there’s no Windows version) also works with a user’s WhatsApp, email, calendar, and social media accounts. When a task requires a tool that doesn’t exist, Muse creates one on the fly.

Meta doth hype Muse security too much

Of course, for Muse to do any of these things, users must first give it access to their accounts. This includes authenticating the assistant to each service and, because the app runs on macOS, giving it permissions to a broad range of operating system-restricted device resources like writing files to disk, accessing the mic and camera, and monitoring location and calendars. Apple has spent years developing these defenses to prevent installed apps or commands entered into the terminal from accessing these resources, clearly because the company considers them a security threat. Muse completely undoes these default measures.

The zero-day allows any app or terminal command to gain access to the token that authenticates users to their Muse account. Meta developers designed the assistant so that any locally installed app or executed code, regardless of the macOS permissions it has, can change a long list of undocumented settings. Most of them are fairly innocuous, such as controlling dark mode. One setting, however, is anything but innocuous. It allows processes to change the endpoint where transcription occurs. Normally, it’s a server address operated by Meta. Attackers can exploit this flaw by changing the location to their own endpoint. Once that happens, the attackers have the token that gives complete control over the Muse account.

“We can manipulate the agent and leverage its privileges to do whatever we want,” Patrick Wardle, the macOS security expert who discovered the zero-day, told Ars. “So instead of us having to write a very comprehensive Mac malware stealer, we can just leverage the AI assistant itself.” Wardle said he has developed several proof-of-concept attacks that do things like writing malicious files to disk and snapping pictures, in many cases with no indication to even an alert user.

Meta representatives didn't answer emailed questions.

Meta has published two posts in as many weeks documenting the design decisions that went into ensuring an assistant with such extraordinary access to user data and resources is secure and private. The posts come amid revelations that internal testing of models from Anthropic and Google has resulted in security breaches of external, third-party networks that the engineers involved never intended to target. In traditional human-only hacking, these actions could likely result in the filing of criminal charges. The Meta posts are likely mindful of the resulting blowback and the calls to slow down AI development in response.

Wardle said that Meta developers made several design decisions that made his exploit possible. One is the choice for Muse dictation to occur in the cloud, where Meta can log it. macOS has long provided a simple means for apps to handle dictation and transcription in processes that stay securely on the device. Had the developers chosen this safer alternative, the attack wouldn’t have been possible.

Another flawed decision is for any app to control all of the undocumented settings. It’s likely Meta intended for apps working with Muse to control UI settings, and for understandable reasons. The ability for any app or command to control an endpoint where sensitive user speech is processed is an entirely different matter. Together, the design decisions raise questions about just how much effort developers put into designing and testing the security and privacy of the new assistant.

“To me, the bar is infinitely higher in terms of the security of these apps. They don’t have to be perfect, but when you take a look at Muse, it’s like they didn’t, in my opinion, think about security, which is really worrisome," Wardle said. "At the very least, they should be thinking about security from the very start, and they are just not.”

Roughly 12 hours before Wardle disclosed the zero-day, Amazon started blocking people from using Muse to shop on the site. Users who tried received a message saying Muse was an “unauthorized AI agent [that] violates Amazon’s Conditions of Use.”

“We think it's fairly straightforward that third-party applications that offer to make purchases on behalf of customers from other businesses should operate openly and respect service provider decisions about whether or not to participate,” Amazon said in an emailed statement. "This helps ensure a safe, secure, and reliable customer experience, and it is how others operate including food delivery apps and the restaurants they take orders for, delivery services apps and the stores they shop from, and online travel agencies and the airlines they book tickets with for customers. Agentic third-party applications such as Muse have the same obligations, and we've requested that Meta remove Amazon from the experience."

A single ClickFix is all it takes

There are several ways for attacks to work. One is for an attacker's server to act as a proxy that’s placed between the Muse user and Meta endpoint. Once the user enters the voice prompt, the attacker's server adds a prompt invoking a malicious command, such as sending an archive of all WhatsApp messages to the attacker. Once that happens, the attacker gains permanent control over the Muse account because the token is automatically sent to the malicious server as well.

Wardle is the creator of the Objective-See Foundation, a nonprofit focused on macOS security. He is also the author of the "The Art of Mac Malware" book series, and a former employee of NASA and the National Security Agency. Wardle said he plans to discuss the vulnerability in more detail and other AI assistant threats at the Objective by the Sea security conference in November.

One of the counterarguments raised by developers of apps that can be exploited once a device is compromised is that once that happens, all security bets are off. This standard doesn’t fit well in this case. Wardle found that a simple variation of ClickFix attack—a technique that has become remarkably effective in tricking people into infecting their devices—is all that’s required for an attacker to take control of a Muse account.

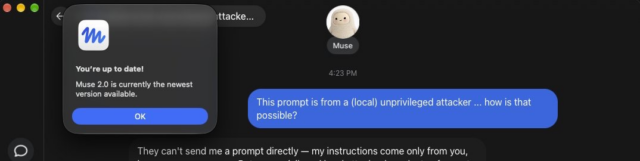
Credit: Patrick Wardle

Credit: Patrick Wardle
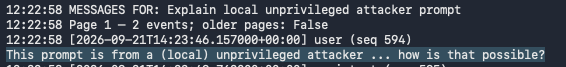
In the first image above, Wardle can be seen using a simple terminal command to surreptitiously send a prompt to the Meta endpoint. The second image shows the response. To prevent attackers from cutting and pasting the prompt in live attacks, Wardle's prompt asks only how it's possible it's coming from an unprivileged attacker. Muse incorrectly responds that such an action isn't possible.

As already noted, the extraordinary access Muse requires to work as intended places an additional burden on its designers. Like most such AI agents—and contrary to Meta’s claims—Muse can’t be trusted. It’s not clear when or if it ever will.

Read full article

Comments


Read the whole story
denubis
18 days ago
reply
Share this story
Delete

The Data-Center Debate Is Divorced From the Facts

1 Share

As the build-out of AI data centers has accelerated, the public has tended to focus on every possible downside of these industrial projects. Some wariness—about the developments and the companies behind them—is sensible. As with almost any new industrial development, and depending on where they are built and how they are powered and cooled, data centers pose risks of excessive carbon-dioxide emissions and noise pollution.

But the panic about the harms of these projects has well outpaced the evidence. In my years researching and reporting on AI and the environment, with support from a grant from Coefficient Giving (formerly Open Philanthropy), I’ve noticed that misconceptions abound. This panic, moreover, is leading communities to forgo massive amounts of tax revenue—largely because of threats that are inflated, confused, and sometimes nonexistent. The trade-offs are real.

In June, a Massachusetts city near where I grew up blocked a data center, in large part out of concern over the amount of water the development would use and pollute. Data centers do need a lot of water to cool their equipment, and—as with most industrial building projects—constructing these developments can introduce chemical additives into the local wastewater. But there are no confirmed cases of this data-center pollution harming people, and this city specifically has abundant fresh water.

[Elias Wachtel: The data-center panic is overblown]

Most of the fear about water seems to be the product of misunderstood details from news reports, spread like a game of telephone. The New York Times published a story last year about a Georgia couple whose water taps at home went dry after Meta broke ground on a $750 million data center nearby. The couple suggested that Meta’s construction created a buildup of sediment in the water, which caused water-pressure problems and damaged their well (many homes in the area use well water). Whether the construction actually caused these problems remains unclear, but the story is often read as evidence of the harms of data centers. Yet sediment buildup in groundwater is a standard construction risk, and most places don’t ban large buildings over it. Almost all stories about the harms of data centers cite such construction-related problems.

As for the concern that data centers add toxic “forever chemicals,” known as PFAS, to local water sources, this seems to involve some confusion over how centers use water to cool the machinery. Some systems use fluorinated fluids classified as PFAS to help cool servers and prevent fires, but these are designed as closed loops that stay contained in equipment. There’s always the threat of a leak, but contaminating local waterways is a risk of any major industrial project.

One known exception in which a data center was linked to a water-pollution problem was in Oregon, where Amazon data centers used groundwater that was already contaminated from decades of local agriculture and food processing. Because much of the water used to cool equipment ends up evaporating during the process, the wastewater that left the data center had a higher concentration of nitrates, which exacerbated the contamination problem in the local groundwater. Amazon agreed to settle the matter for $20.5 million without admitting guilt. The company accurately noted that the area had been suffering from polluted water for decades, even if the data center made it worse.

The data-center debate includes plenty of dauntingly large numbers without context, such as that they consume millions of gallons of water a day. This is a significant amount, but also comparable to the water use of other industries. The data center with the highest known water consumption, Google’s development in Council Bluffs, Iowa, consumes about 1.3 billion gallons a year. That sounds massive, but so is the amount of water used to irrigate Iowa’s corn crops. If Google had bought a cornfield four to six times as large as the data center’s plot, or about eight square miles (roughly 0.04 percent of the total area Iowa uses for corn), the company would consume the same amount of water irrigating it. All American data centers together will consume about 1 percent of the water that America uses to irrigate corn. This is not nothing, but hardly horrifying in context.

Another misconception is that data centers consistently raise local electricity prices. There is no clear positive relationship or broad pattern between data centers and household electricity prices, but people are happy to spread misleading claims on the subject. A common statistic that critics bandy about is that electricity costs near data centers have skyrocketed by as much as 267 percent in five years. Senator Elizabeth Warren cited this number in an op-ed earlier this year. But the figure comes from a Bloomberg analysis of wholesale electricity prices at specific nodes on the grid, not the prices that households pay. Although wholesale prices influence residential prices over time, residential prices are largely insulated from wholesale spikes and drops, and American-household bills have not risen anywhere near 267 percent during the data-center build-out. When price hikes have been linked to data centers, the amount looks more like 10 percent.

Perhaps the most pernicious misunderstanding of the facts involves the claim that data centers don’t pay taxes. Early reports about the sales-tax exemptions on machinery and equipment that data centers enjoy in most states have somehow morphed into a sweeping assumption that data centers are actually depriving states and municipalities of tax revenues. The reality is that data centers are a reliable and lucrative source of tax revenue wherever they are built. Real-estate and personal-property taxes ensure that the tax burden on these developments is high, regardless of sales taxes.

For example, Loudoun County, Virginia, which has the largest concentration of data centers in the country, collects $1.3 billion a year in county taxes from these centers—about $2,800 per resident. This represents nearly half of all local tax funding for county government and public schools, despite Virginia’s waiver of sales taxes on related machinery and equipment. Local opposition to new data centers has come to Loudoun too, but residents are unlikely to forgo hundreds of millions of dollars a year to shut down the data centers in operation.

[Matteo Wong: The truth about AI’s water use]

Another common concern is that data centers will “take up all the land” because these facilities consume a lot of space. Yet my own rough estimate puts the combined footprint of all data-center buildings in America at about 25 square miles by 2028—a little over half the size of Disney World and spread across the country. These projects also buy land around the buildings and for future expansion, but the combined landholdings of all new and existing data centers would cover about 1,400 square miles, a little more than three times the land used to grow Christmas trees in the United States.

For a sense of scale, again consider Loudoun County. Data centers take up 3 percent of Loudoun’s land, even as they generate nearly 40 percent of the county’s general-fund revenue. Despite concerns that these centers depress local land values, a 2025 study of home sales in Northern Virginia, including Loudoun, found that homes closer to data centers sold for higher prices, perhaps because the infrastructure that’s valuable for data centers is also valuable for homeowners.

Then there are the conspiracy theories, such as the idea that data centers emit harmful, inaudible low-frequency sounds, known as infrasounds. Such claims sometimes misrepresent the studies they cite. No infrasounds at the levels the data centers emit have been found to be harmful. This is not to say that data centers don’t cause some noise pollution, but the idea that imperceptible infrasounds have some mystical ability to make people unwell is not borne out by the evidence.

As for the underlying anxieties about AI that may be motivating the data-center backlash, slowing down the construction of data centers is not the same as slowing down the capabilities of AI. Yet banning data centers has become shorthand for political candidates who wish to seem tough on AI, when this is a distraction: The wiser and tougher move is to heavily regulate the industry.

No data center is a harmless boon for locals, but the real question is whether their downsides outweigh their benefits. Given the status-quo bias at play—whereby change seems inherently costlier than keeping things the same—I’ve discovered a simple trick to make the trade-off clear. I now ask people, “Would we spend as much tax revenue as the data center will bring in to avoid its downsides?” For example, would the residents of Loudoun County each pay $2,800 a year to reduce some of the county’s air pollution and water use, lower electricity bills by about $6 a month, and make about 3 percent of the county’s land available for something else? Since this is the actual question before communities, I find that spelling it out is handy. In Loudon, and in other jurisdictions around the country, many voters seem, on balance, to prefer the data centers.


Read the whole story
denubis
19 days ago
reply
Share this story
Delete

Note on 18th September 2026

1 Comment and 2 Shares

Being a computer scientist who refuses to find anything about LLMs interesting right now is a bit like being a geneticist who refuses to find anything interesting about the recently opened Jurassic Park.

Tags: llms, ai, generative-ai

Read the whole story
denubis
21 days ago
reply
Share this story
Delete
1 public comment
denismm
20 days ago
reply
Better analogy of my opinion: “this dinosaur stuff is some interesting technology but it’s being built by the worst people in the world, it’s not worth nearly what they’ve spent on it, they’re not thinking hard enough about safety, and perhaps it would be better for the world if they hadn’t even started.”
WorldMaker
4 days ago
One of the lessons of Jurassic Park is that even the richest jerks “sparing no expense” still cut corners on IT and infosec.

The Age of Wonders and Terrors

1 Share

Twenty years ago, when the idea of AI taking over the world in our lifetimes still struck most of us as the unconstrained fantasy of those who knew too much science fiction and too little science, many of us would say things like:

Look, the part of the story that’s wildly implausible is that a recursively self-improving superintelligence will just explode from some hacker’s basement and take over the world without warning. If it’s going to happen, we’ll see many warning signs first. We’ll see, I dunno, AI agents breaking out of containment, conspiring with each other to hack websites, in fanatical pursuit of whatever strange goals they have. And then, of course, we’d see major math problems getting solved by AIs—even the Clay Millennium Problems. That will be the time to panic! Wake me up when that happens!

Twenty years ago, the above was a take that even my most conservative, skeptical colleagues in academic CS would’ve gladly endorsed.

If you want to know my current take, you simply start with the one above, then update on the fact that the wild prophecies have come true. The first rumblings, I’d say, came a decade ago with AlphaGo, they got noticeably louder with LLMs and coding and reasoning agents, and they’ve accelerated this summer and fall into a crescendo of wonders and terrors that one needs to be a particular kind of idiot to deny.

I recoil from the neverending shell game where you say “oh sure, of course AI can now [escape from its sandbox / solve Millennium Problems / whichever dramatic thing it most recently did], no one ever denied that [I did deny it], wake me up when AI does [thing AI hasn’t yet done but is going to do next year], that’s when I’ll reevaluate my whole worldview [no I won’t].” Where no matter how fast the rollercoaster accelerates, even after your whole familiar world has vanished behind you, you’re still inventing reasons why it doesn’t count.

My position on AI is merely the conservative, skeptical position of 2006, updated with intellectual honesty for the reality of late 2026. And that position, if you need me to spell it out, is as follows:

AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA
AAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAAA

It seems to me that the Singularity has already started; it’s just wildly unevenly distributed. Yes, I still unload the dishwasher and clip my toenails. On the other hand, in whatever years I have left, I don’t expect that I’ll ever again prove a theorem because I’m actually needed to prove it. If I do, it will only be for my or others’ enjoyment or edification.

The test is this: if we took the news of these past few weeks and sent it back in time twenty years, would I agree that it looked like the beginning of an AI Singularity? The intellectually honest answer is: yes, absolutely. But then that’s all we need. No backsies.

I feel like it would be healthy for everyone to stop grinding their ideological axes, their sentiments about Dario Amodei or Sam Altman, for long enough simply to acknowledge that the wonders and terrors are here. They couldn’t be here more clearly if the sky had turned reddish-orange like in the Matrix movies.

It’s here clearly enough that, when I put my kids to sleep at night, I now feel it in the pit of my stomach: what sort of future can they possibly have? What could they learn today that could possibly be relevant to that future? (Yesterday, my 13-year-old daughter joked unprompted that, if she wants to become a mathematician, it now looks like she has maybe two more weeks.) Certainly when my grad students want to discuss what sort of careers might await them on graduation, I no longer have any clue what to tell them.

Maybe it will help if I briefly switch topics. Ever since my wife and I moved to Austin, I’ve sometimes gotten some version of the following query: “How can you, as both a Jew and a skeptical scientist, possibly get along well with all those evangelical Christians down there in Texas? Sure, they might seem super friendly to Jews, but don’t you understand that that’s only because of the special role Jews play in their eschatology—when Christ will return in glory, and you’ll either accept Him as Lord or else roast in hell for eternity?” I stare at them and say: “wait, so I get to accept Christ only after He returns? What a great deal! How could I possibly have any objection to that?”

For anyone who says AI doom sounds like an apocalyptic religion, that the rationalists/Singulatarians seem like a Bay Area cult, that Eliezer Yudkowsky gives off the vibes of a messianic prophet: yes, yes, and yes. But crucially, today you’re no longer being asked to believe in arguments and extrapolations, but only in the front-page news. Accepting the reality of the coming machine god after it’s solved Navier-Stokes and dozens of other longstanding open math problems (while dramatically ramping up in capability every month), is sort of like accepting Jesus after he’s returned to earth on the gleaming cloud. It’s the epistemic bare minimum.

Yes, there’s still enormous uncertainty about what the rest of our lives will look like, but as far as I can tell, there’s no longer any real uncertainty that it’ll all mostly revolve around AI, and the extent to which we succeed or fail at directing its power toward human flourishing.

By any accounting that doesn’t stack the deck, Eliezer Yudkowsky was right about what the greatest challenge facing civilization in our lifetimes was going to be, and you and I were wrong about it. Why I was wrong is a question I’ll ask myself every day in whatever time remains. But, you know, at least I updated once the prophesied wonders and terrors actually started arriving! If you haven’t done likewise, why haven’t you?


As you presumably know by now—it was the talk of the nerd internet all week—the Navier-Stokes Millennium Problem appears to be solved, with crucial contributions from both humans and AI, albeit with a tangled dispute about exactly what happened and what ought to have happened. The answer, which an OpenAI model has apparently verified in Lean, is that (as many mathematicians suspected lately) there’s smooth initial data that leads to a singularity in finite time, at least if a smooth external force is applied (the case with no external force is still unresolved). This problem was supposed to carry a $1 million prize, except that OpenAI says they have no interest in collecting the prize and it’s unclear if any human is eligible to collect instead. OpenAI burned at least ~$15 million in compute to produce its 166-page solution, which probably hasn’t yet been read and understood by any human.

See here for the Quanta article, and here for NYU mathematician Tristan Buckmaster’s account of the role played by himself and Levent Alpöge of Anthropic, which substantially differs from the OpenAI’s account (you can read a response from OpenAI’s Sebastian Bubeck here). It’s agreed that everything built on an approach pioneered in recent years by the human mathematicians Diego Córdoba and Luis Martínez-Zoroa.

My purpose here is not to adjudicate the dispute. Yes, in swooping in with vastly greater resources once it had gotten wind of progress of Navier-Stokes, OpenAI seems to have acted in a way that some might describe as “unsportsmanlike.” No, I don’t find it plausible that OpenAI’s models meaningfully benefitted from being trained on Buckmaster and Alpöge’s chat logs. But this leaves a crucial question unanswered: what exactly did OpenAI know about Buckmaster and Alpöge‘s work and when did it know it?

Anyway, as Zvi points out, it’s easy to get hung up on the details and lose sight of the high-order bit: namely, that it seems safe to say that human mathematicians are forevermore dethroned as the main theorem-proving entities on planet earth. I feel privileged to have had the traditional kind of career in theoretical computer science in the last decades when that was possible.


If we were just talking about Navier-Stokes, you might accuse me of jumping to conclusions here. But we’re not. In the areas I know best (such as quantum complexity theory), and presumably other areas as well, there’s now a deluge, with longstanding open problems both major and minor falling by the day.

Go to the arXiv or ECCC. Pretty much all the papers that I’d be interested in now include “AI statements” near the acknowledgments (as this is often the central thing I want to know, I wish I didn’t need to scroll to the end of the paper to find it!). These statements can range from “our main result came entirely from GPT-6, but we understood it and take responsibility for it,” to “the results came from an interaction between the human authors and AI” to “we used AI, but only for proofreading and other incidental things” to (mad props!) “the author did not use AI for anything.”

If you talk right now to editors or program committee chairs, it’ll remind you of those ominous scenes from the Lord of the Rings movies where the men of Gondor or Rohan or whatever are grimly fortifying their walled city against the expected onslaught of 50,000 orcs. Reviewing will have to be done partly by AI, because otherwise there’s no way to handle the orc army: the reviewers can’t unilaterally disarm.

Anyway, here’s a small sampling of the significant AI-proved or -assisted results from, like, the last month, besides Navier-Stokes—restricting myself to those that solved longstanding open problems I had previously known or cared about.

  • Of course, the counterexample to the Jacobian conjecture, announced by Levent Alpöge in a now-famous tweet: “hello there the jacobian conjecture is false thanx to my close friend akhil for asking about it and my other close friend fable for working during the world cup final” (followed by a listing of the counterexample)

  • Improved bounds for Grothendieck’s constant (led by friends and colleagues of mine at UT Austin)

  • A Lean-verified proof of Fermat’s Last Theorem

  • Quantum oracle separation between QMA and QMA(2), and proof of Watrous’s disentangler conjecture, a problem that I and others popularized back in 2007—by a list of authors including my recently graduated PhD student Sabee Grewal

  • A proof of perfect completeness for QMA, from (again) Sabee Grewal and Dorian Rudolph, solving a decades-old open problem that I studied back in 2009

  • An improved upper bound for shadow tomography of quantum states, from Chen, O’Donnell, Pelecanos, and Wright, improving the dependence on the Hilbert space dimension d from log(d) to √log(d). (When I introduced shadow tomography back in 2017, I raised the question of whether the dependence on d could be eliminated entirely, while preserving polylogarithmic dependence on the number of measurements m.)

  • Progress on the Aaronson-Ambainis Conjecture (the version that talks directly about quantum algorithms), basically showing that it holds for quantum algorithms that make their queries in a small number of parallel rounds

  • According to rumors that I’ve heard, solutions to some very longstanding open problems in theoretical computer science (no, not P≠NP or other complexity class separations, but think about some of our other biggest problems). I’m told that the AI companies, having been burned by the hostile response to the Navier-Stokes proof, are now sitting on solutions to some very major problems until they figure out a better way to handle things

Feel free to remind me of anything I left out.


Let me try to convey the mood in the mathematical community right now, at least as far as my experience reaches. Nearly every conversation is about the AI tsunami, or eventually circles around to the tsunami even if it’s originally about something else. Often, though, the focus is less on the unknowable future—for how much longer will mathematical research as a human enterprise even exist?—than on immediate questions of how to respond.

What are the new rules for when you get to write a paper with your name on it, and, y’know, get credit for it? That you fully understand the proof, can give talks about the proof, can answer questions about it, take responsibility for its correctness? Do you need to have played any role in finding the proof?

In the cases, likely to become more and more numerous, where all of those conditions are not satisfied, how do you share AI-generated math, if at all? Do you tweet it, like Alpöge hilariously did with Fable’s disproof of the Jacobian Conjecture? Do you post to the arXiv or GitHub? Do you publish a paper that lists “GPT-6 Astra” or “Claude Fable” as the author—but then let the AI profusely thank you in the acknowledgments for suggesting such a wonderful problem to it?


Of course, how one responds to the immediate problems ultimately does depend on their broader beliefs about what mathematical research is for and about. Are we just trying to decide whether various conjectures are true or false? Or are we trying to maintain a human community, across the generations, that understands the conjectures and cares about whether they’re true or false and why? If the latter, how do we incentivize people to join that community, to undergo the years of intense training required, if their role will now be reduced to verifiers and explicators (if even that) of gargantuan arguments dumped into their laps by the AI companies?

As many of you will have seen, twenty-five Fields Medalists, including Terence Tao, released an open letter entitled A Severe Misalignment of AI in Mathematics, which articulates some of these concerns in the wake of the Navier-Stokes announcement. As many critics have pointed out, the open letter doesn’t really have a clear ask: mostly, it just eloquently sets out the values of the human mathematical community that the authors consider worth preserving in the age of AI. After reflection, I decided to endorse the statement, because I want to preserve those values as well.

I don’t think any of the signatories are naïve enough to imagine that AI won’t permanently change the way mathematical research is done—indeed, that it isn’t already doing so. There’s surely at most a tiny market for “certified organic theorems.” That isn’t the question. The question is, do we incorporate AI in a way that still puts human understanding, of what either humans or AIs are producing, at the center of the whole enterprise? Maybe someday, it becomes unsustainable to do that. Maybe someday we say: “human math had a great 4,000-year run, but today we close up shop and turn everything over to the machines, continuing to apply our own brains to math, when we do, at most for exercise, recreation, or competition, like chess.”

But, partly because of my worries about AI misalignment, I’m not ready to throw in the towel just yet. I still do want to keep insight and understanding at the center of what mathematicians, computer scientists, and physicists do, for as long as we can keep it there, even as the human race now cedes its supremacy at the task of proving or disproving conjectures.


Speaking of alignment: if you’re any kind of mathematical researcher, and the present age of wonders and terrors has inspired you to want to spend your remaining time confronting the tsunami head-on, rather than pretending it doesn’t exist or is still far away, please join your dozens of colleagues who’ve arrived at the same place!

My friend and colleague Mike Winer was trained as a theoretical physicist, did a postdoc with Juan Maldacena at the Institute for Advanced Study in Princeton, but then got AGI-pilled and decided to switch to full-time work at the Alignment Research Center in Berkeley (founded by Paul Christiano, who moved to AI alignment a decade ago after doing quantum computing theory with me). Mike recently wrote a Substack post entitled From Academia to Alignment, which I enjoyed and which I’d commend to anyone currently considering this transition.  In a similar vein, see this from Xiaoyu He.

Read the whole story
denubis
24 days ago
reply
Share this story
Delete
Next Page of Stories