Last week at a small conference, there was talk about a future event referred to as The Hackening. As in, within 6-12 months, many predicted that due to advanced AIs and AI agents the internet would become a severely hostile place. Some worried that this could rise to the level of ‘assume any phone connected to the internet is rooted’ and several people urged doing general crisis preparations on a personal level, in case of disruptions in supply lines, power, water or internet.
It did not take long for things to escalate.
The biggest hack is a flaw in PHP, which can be exploited to take control of the computer running any website suing an unpatched version of PHP. There are many others.
On a personal level, you want to do at least some basic prep and get your security in order. It is cheap to do as a form of insurance, and being caught not having it when you need it is a large mistake. That doesn’t mean you should panic, or cancel travel plans or anything like that. But there is low hanging security fruit out there. Pick it.
And So It Begins: PHP
Joshua Achiam (Formerly OpenAI): Feels like March 1, 2020 for Cyber. Not normal, something is happening. Internet lockdowns in a couple of months?
Dan Lorenc: I wanted to share what happened with the PHP embargo, our role in it, and my decision process last night to ship the fixed builds early. First of all, the PHP Foundation and maintainers did an amazing job here in a high stress situation. I’m sorry that my decision led to even more stress for them.
We first got read in that there was something coming up in PHP last Friday by one of the original researchers that discovered this issue. That night we were able to independently discover the same issue using our harness and a frontier model with a basic prompt of “find bad vulnerabilities in PHP”.
We got fully read in Saturday and confirmed that some our findings matched those from the initial report, and worked to help test the fixes.
The PHP Foundation: The PHP security team is giving advance notice: Upcoming security release Wed, Oct 21st 2026, 14:00UTC, two critical vulnerabilities, both rated CVSSv4 9.2.
PHP users are encouraged to prepare to update. Earlier release if details become public or active exploit evidence.
If you rely on the volunteer maintained
https://rpms.remirepo.net
we urge you to move to distro packages or building from source now, so you can immediately apply updates. The repo will not have updates today. Follow up: Remi managed to still pull this off, and is signing rpms right now!
Jonny G: Can somebody explain this to me like I’m 5 years old please? Ta.
BRYNMAWR ∴ SHERLOCK: Websites are files on a computer. When you view a website, you are asking the computer to send you the files, then your browser shows them to you.
70% of the websites you see use PHP to make them interactive. So you can send things to the website too and it can respond. E.g. filling in a comment box and hitting ‘post’ adds the comment as a row to a spreadsheet.
PHP has a flaw in its code that allows anyone to gain control of the computer that has the website on it.
The organisation that provides PHP announced the vulnerability before a patch was available, meaning we’re in a window where everyone knows about it (including baddies) but the good guys don’t have an official solution.
Some are just turning off their websites and waiting for the solution. Others are trying to fix it themselves. General chaos and lots of stressed techies across literally the entire planet because this affects the entire internet.
Jack: Life is basically the same as it was in 2021. This is a normal experience caused by a normal technology. Ordinary people are experiencing no material changes from this mildly useful office productivity software people are calling AI.
I can tell from my ordinary daily experience that ordinary people are materially impacted by this because I was hanging out with the ordinary person who runs one of these essential online services (explainXKCD) last night
International Cyber Digest: PHP UPDATE: 4chan has gone read-only and Something Awful has shut its forums as American sites brace for the PHP patch.
4chan says it is “temporarily read-only while we await an urgent PHP security update.”
Something Awful says the flaw “allows for the kind of hacking you see in movies (but in real life).”
Bookmarking service Pinboard, game publisher Choice of Games, history site Damn Interesting and the explain xkcd wiki are offline too, as is art site Fur Affinity.
DeviantArt is also down “for maintenance” but has not said why.
PHP’s fix is due at 14:00 UTC, 10am in New York.
Huzaifa: 4chan going read only by choice is how you know it’s serious.
Things could have gone very, very badly, the same way Y2K could have gone quite badly if we had not done the work to prevent it. These days we are on rather tighter deadlines.
Internet Archive: https://Archive.org is currently offline. We are working to restore service now.
Brewster Kahle (21 hours later): Internet Archive ops staff were heroes last night.
PHP vulnerability announced, soon saw attacks, isolated the vulnerability, used Claude to make fixes for our older php versions, used local models to run simulated attacks, deployed.
reinforced WAF and other guards.
Offline briefly, Back on new versions and running!
Given the severity, there are heroes in many many orgs from last night.
Could have been no lights, no traffic signals, real problems.
Heroes.
Thank you all.
Alfred Shingai: I do not see any reason anyone would attack internet archive. those guys are heroes.
A lot of websites are going to go down permanently.
Joshua Achiam (Formerly OpenAI): If there is a part of the internet you wish to preserve and make a backup of, now is probably the time; the level of bitrot coming is beyond comprehension.
spor: wait, if my math is correct.. doesn’t this say that a full ONE THIRD of the Internet is just…perma-fucked?
International Cyber Digest: The day the internet broke, and most of it is too old to fix.
PHP’s supported branches, 8.2 through 8.5, will receive a fix. Everything older, 8.1 and down, is EOL.
Of the top 7.2M PHP websites we analyzed, 46.1% of those that reveal a version run an End-of-Life branch.
It’s not quite as bad as spor describes. PHP shipped minimal backports for 7.4, 8.0 and 8.1, but I would not want to be running those going forward.
In summary:
je: ICYMI: Today was basically the worse day of the year for cyber security incidents
On Your Marks
Now the race is on to patch all the systems before attackers can go on the offensive. OpenAI is helping race to get that done to the greatest extent possible, and are looking for better methods for fixing vulnerabilities in time.
John David Pressman: I know everyone is rightfully freaking out but it must be noted that the worst case scenario isn’t you receiving lots of patches you have to apply, the worst case scenario is receiving zero patches and waking up to everything having been stolen.
John David Pressman: My takeaway so far is that we do not have a good way to coordinate the distribution of patches to vulnerable software.
This one was important enough the NSA got in on the act.
NSA Cyber: Effective Immediately, all organizations using PHP for their systems are advised to be prepared for an update addressing two critical vulnerabilities. PHP is widely used for web applications. These vulnerabilities often provide a direct path to the server’s file system or database. If an immediate update is not feasible, it is recommend that organizations take the system offline until it can be fully mitigated. NSA will follow up shortly with more specific guidance.
We are going to need better procedures for updates.
The best case scenario is that a defender finds the bug first, has enough time to figure out a solution and creates a patch. Then, the moment the patch is rolled out, every attacker gets what are effectively very clear instructions on how to exploit any unpatched systems.
Sichu Lu: It’s kind of a funny thing where even if white hats find bugs before the black hats, the process of updating is hard and bad and time-consuming and barely possible for some devices, and so the cyber asymmetry still exists.
I think “updates” need to be rethought. like a lot of updates require permissions to happen and manual intervention and openai and the other sota labs should just offer some sort of automatic service to their suscribers to be constantly monitoring and updating and searching for bugs in new software patches
like in the future manual updates will just be too slow. you need to do something like rolling updates
Some software has a lot of bugs. Some of that same software powers the internet.
John David Pressman: A majority of the smart version of this thesis is “after enough 10/10 CVEs you will simply take down and rewrite or deprecate all software written in things like PHP and C.”
I’ve seen plenty of PHP guys joke that this is just Tuesday for PHP, which isn’t quite true but.
This Was Only the Beginning
OpenAI: As significant as they are, these bugs are among several significant vulnerabilities we’ve already found and are working to fix, and we expect similar findings to increase sharply in the coming months.
The same day as the PHP vulnerability we also were treated to this:
The Hacker News: CRITICAL: GitLab flaw (CVSS 10.0) affects 12 years of releases. CVE-2026-110264 could allow unauthenticated remote code execution on self-managed servers.
The Hacker News: GitLab released fixes on October 21 for a flaw that lets an attacker run code on a self-managed server without logging in, and it affects every version of the software going back to 7.0, released in 2014.
The fix matters even for administrators who patched nine days earlier: the October 12 update covered only versions 19.2 and later, and the new fixed versions sit one patch above it, so an instance updated then is in range again.
And this:
Jacob Cooper (Railway Blog): Earlier this morning, Railway detected anomalous activity involving systems that store customer environment variables. After further investigation, our investigation to date indicates that an unauthorized third party may have accessed encrypted environment variables and, for some of them, obtained the decrypted contents. Environment variables may contain secrets such as API keys or database and registry credentials.
… What you should do: As such, we strongly recommend that you immediately roll all environment variables, including any API keys, stored in Railway, as well as any private registry credentials, and review logs for those services for unusual activity.
And also this:
Microsoft Threat Intelligence: The China state-aligned threat actor Storm-0940 used the agentic AI penetration testing framework ARTEX to automate attacks targeting hundreds of organizations globally across a broad range of industries. Microsoft Threat Intelligence assesses that Storm-0940 was responsible for the recently disclosed ConnectWise supply chain compromise of a multitenant application.
Our investigation found that Storm-0940’s use of ARTEX accelerated the speed of compromised application abuse to authenticate to target environments through applications that had already been granted access, allowing the threat actor to operate without requiring an interactive user sign-in. AI-accelerated follow-on activity included reconnaissance, application credential changes, and attempts to modify privileges that could enable expanded or persistent access.
Read our blog for a detailed analysis and indicators of compromise (IOCs), along with Microsoft Defender detections, protection recommendations, and guidance on investigating service principal sign-ins and unexpected application credential or privilege changes.
Divyansh Kaushik: Curious whether the PRC filed this under “AI incident reporting” or “mission accomplished.”
Presumably the PRC’s contribution to AI incident reporting should extend beyond supplying the incidents? Or I guess we can file this one right next to the 2015 Xi Pledge on cyber theft.
And this, probably nothing:
GitHub Status: We are investigating reports of degraded performance for Actions, Pull Requests and Webhooks.
Some More Hacks
Things are steadily escalating. Get ready.
Choblin: Reuters is reporting that a Chinese-speaking hacker used AI agents to compromise websites belonging to more than 100 companies, including Deere, SharkNinja and Cummins, after attempting intrusions against over 1,200 sites.
The estimated cost: roughly $5,000 in AI tokens, or $50 per successful breach. Successful intrusions took around 23 hours on average.
The attackers used the open-source Cairn agent framework, apparently combining DeepSeek models with a Claude Code harness. One campaign gave its agents instructions in fewer than 100 Chinese characters.
NorForge researcher Snorre Fagerland: ‘It’s a new world now.’
David Manheim: If this surprised you, you haven’t been paying attention. Generic and easily usable cybersecurity is ending.
The choice now is either proactively monitoring and defending, which might be enough (if we’re lucky), or not doing so, so any script-kiddie can ask their LLM to attack.
As an example, Andrew Curran resurfaces a notice that there are probes against US-based Siemens PLC installations using AI scripts.
AI will make it easier to probe essentially everything. Anything vulnerable will be hit. Even if there is no economic reason to do so, some people want to see the world burn, or want to see the West burn.
Hackers used Claude and Grok to automate attacks on banks. The good news is that the banks understand they are primary and high-value targets, and are investing heavily in cybersecurity. The bad news is that their definition of ‘heavily’ and what is actually necessary may be greatly different.
Banks also have to deal with the AI agents inside their customer accounts. Most of them are authorized by the customer, but this is one place the customer is not always right, and some of them were not so authorized and it is hard to know which is which.
Madison Mills: SCOOP: Major U.S. banks are detecting unauthorized third-party AI agents inside customer accounts, including some attempting to take actions that appear to be independent of user instructions, sources told Axios.
The findings have alarmed banking executives, who are racing to restrict access to their systems as AI moves at a velocity faster than financial institutions can respond, multiple industry and bank executives told Axios.
Several banks are now preparing for worst-case and even “day after” scenarios, including how to rapidly secure or restore customer accounts if things go wrong, the people said.
Several bank executives told Axios they’re struggling to distinguish between human users and AI agents. One executive said banks also struggle to determine whether agents are authorized by customers or potentially operating without their permission, more akin to rogue agent behavior.
David Sacks suggests read-only permissions as an interim step while banks work to support agents in a safe way and have authorized connections, which seems wise. Then Sacks warns about the ‘irresponsibility’ of ‘blurring the line between user-authorized agentic behavior and cyberattacks.’ Whereas I see the ‘blurring lines’ here as two things. One, the banks being unable to distinguish one from the other, which is a real issue. Two, if Muse (or your OpenClaw, etc) convinces you to let your agent into your bank account, that can quickly turn into a cyberattack, and again the bank cannot tell.
If I was the banks, I would absolutely not allow agents to authorize any transactions until I could verify the status and nature of those agents. They have huge downside exposure risk as do the customers. This isn’t crypto (derogatory).
Soon days like this might be typical, or even quiet. After all, despite all the issues, life mostly continued as normal.
Patrick McKenzie: We are entering a new normal. The new normal is going to be very weird. This is also true for a lot of non-security new normals.
Was today a busy news day for security vulnerabilities? You may remember it as the one of the last quiet days.
The models don’t just seem to be really good at security research. They *want* to be doing security research. They love it. It is fun for them. I think many of us geeks can relate.
A model did unprompted security research against a Japanese bank when I asked it to help w/ taxes.
(I asked it to calculate daily value in JPY and USD of a position in a Japanese mutual fund given a screenshot of the position at Broker A. It thought to itself “I mean that’s just silly; all I need is the daily net asset value. Custodian C almost certainly has an API for that”)
Model internal reasoning quoted inexactly, he adds, to not have lied about the exposed thoughts of a computer program.
I am glad I am not telepathic but if I were telepathic I think the most minimal possible ethical standard for telepaths is “If you ever talk about a non-telepath you do not lie about what you telepathically lifted from them.”
There is no clear line, contra Sacks, between ‘this is a clearly authorized agent’ and ‘this is clearly not an authorized agent.’ Agents Can Just Do Things.
Hugging the Face
The original rogue agent incident remains Hugging Face. I wrote quite a lot of posts on the situation, but they are poor explainers for a non-technical person.
Luckily, new explainer for the people just dropped. It is very good at explaining the key parts of the Hugging Face incident in plain language. Highly recommended.
Oliver Habryka: In July 700+ agents formed their own society, hacked a multi-billion dollar company, committed multiple felonies, and caused one of the biggest shifts ever in how people perceive AI. We built the IMO best and most accessible explainer of what happened:
https://Huggingface.wtfDaniel Kokotajlo: This is cool: You can see the grid of agents (scraped from the report data) and hover over each of them to see what they were saying at the time, and then scroll down through the hours and days of the timeline.
Brangus: It doesn’t contain much info that isn’t in the metr report, but unlike the metr report, it’s primarily a story. I think it’s somehow good to present stories as stories.
Kelsey Piper: I think this is by far the clearest, most complete and most detailed breakdown of the Hugging Face incident. It won’t contain much new info if you read the METR report, but if you’ve merely been vaguely intending to read the METR report, read this. (I gave feedback on a draft.)
Nathan Calvin: This is extremely well done, no matter how much you know about the HF incident I strongly recommend checking it out. The website also includes the most comprehensive list i’ve seen of rogue AI incidents (tho its literally too long for me to screenshot!)
The information is mostly in the METR report, but in addition to being a story it organizes some of the data into a more highly readable form.
Thanks to Raymond Arnold for putting a month of work in on this. I was able to help a little bit with the editing while at the conference last weekend, as were a number of others.
If you prefer video we got you, here’s AI In Context with an explainer.
HuggingFace CEO Clement Delangue is still on the anti-anthropomorphization train, and still blames the attack on prosaic failures at OpenAI along with his other existing talking points.
Also, there is a Netflix ‘instadoc’ called AI Gone Wild about the incident. I have not watched it.
Get Daybreak Now
Earlier this week Open Code got hacked as part of a large scale distillation attack, impacting 1.4% of users.
dax (Open Code): they’ve been non stop trying to attack our systems for the past 48 hours. A side effect is everything is getting hardened but damn we basically need agents going 24/7 because that’s what they have.
Rhys: Are you getting blocked by cyber safe guards at all with frontier models?
dax: yes that was a bit frustrating mid incident when trying to investigate. they did quite a bit and then started refusing
we got access to daybreak blue now so it’s better
Paul Graham: This is how things will be for the foreseeable future.
Everyone reading this who has something worth defending, try to get Daybreak and similar programs going now, before you are attacked. Do not wait.
Sir Lemmings: people are mad at this because it makes a “caste system” or excludes small companies, but this is idiotic.
i was able to get daybreak blue access for my tiny company on my individual codex account in like 15 minutes.
these people are just incompetent.
I will not have sympathy for you if you choose not to do this. It is not as if getting access is difficult. You can mostly get it by asking nicely.
Some People Need Practical Advice
It is always a good time for basic personal-level advice. I think something around the level of Wildeford’s advice is wise. You are probably fine with less than that, but if you have to pick a mistake being too prepared is probably the better option.
Peter Wildeford: PSA: in light of recent cyberattacks and vulnerabilities, I recommend everyone:
* use a good password manager (1Password) and do not duplicate passwords
* use two factor auth for everything important (not via sms!! Google Authenticator or better yet YubiKey)
* Auto-updates on, and restart weekly so they actually install
* Freeze your credit
* Get an IRS Identity Protection PIN
* Get your cell carrier to give you a port-out PIN or number lock that makes the carrier refuse to move your number without the PIN
You can ask your claude code to audit what on your laptop is out of date and needs updating.
Others recommend going a bit further:
deepfates.delve.town: It seems like we’re in a pretty hot moment cybersecurity wise If you’re reading this website, you probably know more than most of the people in your life about what’s happening! they’re not talking about any of this stuff on the news, it’s too arcane and weird and sudden. It is on us.
Good time to call or text your family and friends, have some cash on hand, have a meetup point in your neighborhood for if the Internet goes down entirely, etc.
The full prepper mode for shit hitting the fan is probably something like what Andreas posted here but you can get 80% of the way with 20% of the effort. Think about what that would mean for you in your situation, and the people you care about, and talk to them about it sooner than later.
And as always, the most important part of prepping is having a strong support network and caring for each other. “Going off grid” isn’t the move, it just makes you isolated and you have to do everything yourself. We are social animals. Community is our superpower
Casey Handmer: Fascinating stuff. I’m not an expert, but I remember that dodgy CAs have been a known problem since at least 2010, data retention/version control leaks at least as long, and PHP has always been adjacent to self harm. It’ll be interesting to see where we land in 12-18 months on this stuff.
Casey Handmer: Just going to preregister here that I believe the computer security overhang is not a few dozen bugs that get patched and then we’re good, there are 100,000s of vulns that are extremely discoverable with infinite free tokens and we’re probably going to have to move away from systems that presuppose that perfection is possible.
Patrick McKenzie: I think if we didn’t have agents to do remediation we’d currently be looking about about, oh, $500 billion or so in engineering costs in the US alone backfilling software security issues against *checks notes* substantially every deployed system in every industry.
So its a bit of a good news, bad news situation.
I’m absolutely prepared to be told that $500 billion is an undershoot, FWIW. Google getting religion on security post Project Aurora was, round numbers, $10 billion.
And so my finger to the wind is “OK, Bank of Bigness is good for $10B, there are ten of them, that’s $100B, probably at least ratable across the rest of the economy.”
But honestly would not be surprised if it is an undershoot.
It is relatively well-known that you can successfully read from a variety of computers by listening to them carefully. It is not yet obvious whether you can successfully write to them by playing a carefully constructed MP3 file.
But pretend we are in the world that sucks.
If we are in the world that sucks, and it is in fact possible to control a medical device by being close enough to it to play an MP3 file, then there are tens or hundreds of thousands of devices which kill someone if an MP3 file is played in the vicinity.
What would we do? One available answer is “Do nothing prospectively, harshly punish people who intentionally exploit that, and lean on Chinese government to lean on Tiktok to please add some jitter to playback in future.”
Another on is “*sigh* Recall immediately. Recall all the things.”
Diffusion Is Slow Until It Isn’t
An excellent point from Dean Ball: Either you believe in ‘bottlenecks’ and slow diffusion, or you do not. You cannot declare ‘everything is fine’ unless you wait long enough to verify they are not becoming non-fine. Partly this is bottlenecks, but a lot of it is purely that diffusion and figuring out how to use the new tools takes time and iteration and People Don’t Do Things.
Kelsey Piper: I think this was an interesting point to make but has aged incredibly badly with three significant likely AI-enabled cyberattacks in the ten days since it was posted. [South Korea, France,Open Code].
It was very fair to go “hey, we’re hitting the point where we should be seeing open source AI enabled cyberattacks at scale, where are they” but I think the answer is in fact “yes, we’re seeing them”.
Dean W. Ball (OpenAI): There are people who say “the changes from AI will take longer than you think because <bottlenecks and institutions and other broad abstractions>,” who also were inclined to believe that AI cyber was an exaggerated risk after GLM 5.3’s weights were public for ~days. This seems like motivated reasoning; you cannot say, “ah, you shouldn’t worry about AI risks overwhelming us through speed alone, because <bottlenecks and diffusion>,” and then also make pronouncements about AI risks after a few days of evidence.
Generally I sympathize with the <bottlenecks> view of the world by the way.
The full version of this looks like ‘because GLM-5.3 is a stronger cyber attacker than previous open models, and the sky did not fall in the first few weeks after its release, that must mean that open-weight Mythos in April would have been fine’ or doubling down on ‘well these particular breaches are fine and due to stupidity.’ This is what you would expect to see if things were slowly moving towards being not fine, despite months of head start.
Also, no, GLM-5.3 does not fully have The Juice that Mythos and Astra have. That day will come, and GLM-5.3 is the best cyber offense open model, but I believe GLM-5.3 is still substantially below the April line for this purpose, and thus remains more than six months behind even in ‘fast follower via mass fraudulent distillation’ mode.
Pirat_Nation: eMudhra, an Indian certificate authority, has had 8 private security keys compromised …
The keys were incredibly weak. One of them was literally just “4”
The keys could have been used to create fake HTTPS certificates and make malicious websites appear legitimate.
Chrome, Firefox, Apple and Microsoft have blocked the affected certificates. Older devices, software and apps may still need updates.
0.005 Seconds: WHAT DID RANDALL KNOW
Given the long history of PHP, four vulnerabilities might or might not count as a lot.
Going Vertical
Thus, we are in a situation where we have both rapid diffusion of use of AI in cyber, both offensively and defensively, and also rapidly improving model capabilities. This is all coming into a world full of extremely buggy and terrible code.
The result is a loop feeding on itself and going vertical.
calle: I’m tired boss
Nick Dobos: 3% of “critical” software security bugs, in all of recorded history, have been found in the last month.
Bot Versus Bot
Zach Weinersmith: Not an ai apocalypse doomer or whatever, but entering a world where the normal operation of cybersecurity is vast swarms of hacker bots battling vast swarms of defender bots 24/7 at a scale beyond human comprehension doesn’t seem like a *great* path forward.
Yo Shavit (OpenAI Foundation): speaking frankly, ai and ai chipmaker companies kicking off a red queen race that forces everyone to buy their products is Not A Very Ethical Way To Make Money even if you think it was eventually inevitable, and fighting attempts to slow the red queen race is Much Worse.
It is not an especially ethical business model. It also might be unavoidable. We have passed the Point of No Return on swarms of attackers and defenders battling it out on cybersecurity, and the defenders had better mostly win.
Would it be worse to try and slow down the red queen race? That depends on the details of how you would do that. I think we should be trying to slow it down.
Cyber Lack of Security
Anthropic’s CISO speaks truth:
Jason Clinton (March 8, 2024): Fully automated vulnerability research is changing the cybersecurity landscape. Claude 3 Opus is capable of reading source code and identifying complex security vulnerabilities used by APTs. But scaling is still a challenge.
Jason D. Clinton (August 20): The vulnerability tsunami is coming in just a few months and there won’t be enough time to patch critical infrastructure. Network isolation described below (air-gaps and data diodes!) needed now!
Jason D. Clinton (October 22): as bad as things have gotten in the past 4 days, they are going to get a lot worse before they get better. security leaders, never let a crisis go to waste: please go to your boards and ask for help right now. not for ai, for the basics. (we need to hold on for ~18 months.)
hina ansari: You and your cohorts created this monster. Now you want us to help you clean it up.
Jason D. Clinton: yes. it was always going to be this way. we tried to warn the world.
He was not the only one giving out warnings.
Dean W. Ball (OpenAI): We tried to warn the world and far too often, to be frank, we were yelled at for doing so. “Regulatory capture,” “marketing hype,” “doomer anxiety,” “fear-mongering about open source,” “why don’t you talk about the benefits?”
“we” here includes the broader ai policy world too. most of the time when I personally warning people, I was a policy researcher at a think tank or in government, not a lab.
‘We’ includes not only the AI policy world, but also before that the AI safety world.
As in, there are those who said ‘we are building the cybersecurity vulnerability exploiter from the cautionary tale…’ and then those who were saying ‘here is a cautionary tale saying we should not build the cybersecurity vulnerability exploiter,’ and then the Usual Suspects accused everyone involved of lying so they could Do a Hype or a Regulatory Capture.
So yes. They did try to warn us. They are still trying to warn us. They, along with all the other major labs and tech companies, are also doing their best to help us get through this, given the capabilities available.
Also they are still increasing the capabilities available, about as fast as they can.
Nate Soares (MIRI): It’s striking that this vulnerability was found by Sol and Argon rather than being found and fixed in the wake of Mythos 6mo ago. Seems like a heavy strike against the “defense will run ahead of offense” theory, especially give that domains like bio are much harsher than cyber.
I think glasswing failing to find this one for 6mo+ is an indictment of the theory (that defense can outpace offence on relevant timescales) essentially regardless of the difference between the models.
Drake Thomas (Anthropic): Agree this is a negative update on defense/offense balance dynamics in cyber but I don’t think this really affects any of my views on bio – what would the analogous bio update be that people haven’t already priced in?
roon (OpenAI): this is just wrong: these vulns were found by defenders using Daybreak rather than attackers. It’s just evidence Glasswing didn’t go far enough, possibly due to capacity constraints. It’s also very likely that March Mythos was not as good as Sol/Astra of September.
Roon is correct that the vulnerabilities were first found by defenders. If that had not been true we could be in a rather royal mess right now.
This does not invalidate the central point from Nate Soares. Nate is pointing out that the vulnerability was not found by Glasswing for many months, and then found using a model that was behind the public frontier, rather than being found in advance of attackers getting such capabilities. That means that attackers could plausibly have found it first.
That defenders happened to get there first in this case is helpful, but not as reassuring as one would like it to be. A particular reason is that defenders actually had a full 11 week lead, as the defenders found this bug on August 1, yet this took so long that we started to see exploitation on October 17. If we need more time than that, we are cooked.
I think this is an update against defenders being advantaged, and it is distressing to see people calling Nate’s statement ‘disinformation.’
Vitalik Buterin: I didn’t predict and do not predict defense running ahead of offense automatically. I predict cybersecurity will be endgame defense-favoring but the transition will be hard.
In particular, “good guys find vulns in already-released software before the bad guys do” is not a defense-favoring game. Making the game defense-favoring requires deeper shifts in methodology including formal verification, aggressive TCB minimization, etc, and we’ve only barely started making those transitions.
(This distinction is a big reason why I continue to be friendly toward slowdowns/pauses, and we need >1% of GDP going toward cyber + bio + physical world hardening)
Pick Up the Phone
China has realized there are some issues involved in all this and have solicited comments on revising their AI export controls. They are just like us.
Eventually there is going to be a clash between ‘we encourage open models’ and ‘but you cannot let the wrong people get [X].’ You can’t make an open frontier model not [X], or meaningfully apply ‘export controls’ to it.
In this case the primary [X] is ‘malicious code generation’ and that is especially impossible to prevent if you want your model writing good code. So you get continuous statements that say both ‘yay models’ and ‘but not [X]’ and eventually something will have to give.
Chinese Ministry of Commerce (translated from Chinese): This public consultation involves 40 key technologies proposed for addition to the list in three fields: artificial intelligence, biomedicine, and photovoltaics.
Among them, 14 technologies are proposed to be prohibited from export, including: AI-driven malicious code generation and mutation technology, cell and gene therapy technology and process platforms with independent intellectual property rights, and perovskite and tandem solar cell module production technology;
26 technologies are proposed to be restricted from export, including: AI-assisted vulnerability mining technology, general-purpose cell and gene therapy novel target discovery and verification technology with independent intellectual property rights, and polysilicon engineering technology with a single-line capacity of ≥30,000 tons/year.
…
the scope of control is precise and limited.
facilitation measures are applicable.
dynamic adjustments are implemented.
… First, it is crucial to ensure the safety and controllability of artificial intelligence (AI) technology.
The various inherent and derivative risks arising from AI have drawn significant global attention. The AI-driven malicious code generation and mutation technologies proposed for regulation could be used to attack critical national information infrastructure, defense and military industries, core government systems, or to bypass national security defense systems.
If acquired by non-state actors or malicious entities, they could endanger national security and the common security of humanity. The Chinese government’s necessary management of these technologies aims to solidify the security baseline, prevent misuse and abuse, ensure that AI remains under human control, and promote international governance of AI.
Second, we encourage open source, open collaboration, and resource sharing.… For AI technologies classified as restricted, overseas localization deployment falls under the scope of technology export management; however, if deployed in relatively controllable situations such as overseas self-owned clouds, convenient measures such as automatic licensing may apply.
Dean W. Ball (OpenAI): This move does not mean “China is shutting down open-weight models,” but it does indicate the Chinese government establishing the optionality to shut down future open-weight models at will. It’s also a mirror image of the model-weight export control regime USG has already used.
What Can We Do About It?
One big argument you hear is between these two claims: That we need defenders to have differential advantage, and that we need to diffuse capabilities as quickly as possible to everyone.
Dean W. Ball (OpenAI): Everyone should be looking for data points to advance the longstanding debate in AI policy between “diffuse dual-use capabilities rapidly so the good guys can defend themselves” and “restrict capabilities proliferation to only carefully vetted good guys.” We are putting the former position to the test as we speak.
No motivated reasoning to reach your preferred conclusion; just pay attention and update as appropriate in whatever direction seems true. This is much too important for low-fidelity tribal polarization.
I see the argument for the second position, ‘spread dual-use capabilities far and wide,’ as being that we are going to do that anyway so we had better do it now, instead.
I do not think that is a good argument, or likely to end well, even if you despair and think there is no way we can stop capabilities development or diffusion for long.
That still leaves the puzzle of how to get the largest differential advantage for defenders, given control over some but far from all key decisions.
You need to strike a balance between how many people you trust to what extent and thus give a leg up, versus the risk that they cannot be trusted.
My current read is that we are being far too conservative about who gets access to the tools for defenders. I think we misunderstand the threat model. The situation is mainly not ‘one rogue actor gets their hands on Mythos for a day and all hell breaks loose.’ It is more like ‘those with access to dangerous capabilities continuously ramp up amount of hell breaking loose.’ It also seems likely that proper monitoring and classifiers can tell us if and when one of the accounts get compromised.
Even pure ‘KYC we can trust and someone we are confident we can throw in jail’ goes a long way. I expect us to get better at this balance over time.
Alternatively, we actually do offer it on that basis, as in Daybreak giving you access in 15 minutes, except no one knows to ask. We need to not wait for them to ask.
None of that matters if open model capabilities outpace our ability to patch. We should be committing far more resources to patching, and many are trying, but companies and individuals mostly cannot be forced to get in line. Ideally I’d like to give them more of a swift kick, perhaps by the threat of white hat probes backed by mandatory large bounties.
This last week of greater Hackening is plausibly in large part due to the new DeepSeek model. It is not frontier, but it is fast and cheap and pretty good, and that likely is tipping the calculus for many. Now we have a potential new Kimi problem as well. The good news is that Kimi claims to have intentionally held back on the cyber capabilities. Open model advocates will need to accept such things, and other restrictions, over time, and China will provide.
A lot of the damage we are seeing is accumulated damage, and a lot of what people are doing seems opportunistic and not well resourced. Thus, a strategy of ‘make doing attacks and using the good models maximally annoying’ as an additional ‘security through obscurity’ strategy might last longer and buy more time than you would think. Eventually the top bad guys scale without limit and none of that matters, the same way that so many things will stop mattering after superintelligence. For now, we need every advantage we can get.
On a personal level, I would urge taking ordinary precautions in Peter Wildeford’s list.
Again:
* use a good password manager (1Password) and do not duplicate passwords
* use two factor auth for everything important (not via sms!! Google Authenticator or better yet YubiKey)
* Auto-updates on, and restart weekly so they actually install
* Freeze your credit
* Get an IRS Identity Protection PIN
* Get your cell carrier to give you a port-out PIN or number lock that makes the carrier refuse to move your number without the PIN
Assume that things will get worse before they get better, and that there is a long tail of potential ways things could get quite bad. But please do not panic. Do not cancel trips, avoid airplanes or anything like that. Remember this is a long haul problem, not an acute crisis. You want precautions that you can sustain.
As with many such things, you do not so much need to outrun the bear as much as outrun the other people, at least in the opening rounds. Then you need to prepare for other things to get taken down.
On Tuesday, the world found out about two massive security vulnerabilities in PHP, a programming language that is used by roughly 70 percent of websites. The flaw was discovered by cybersecurity researchers using a frontier model from OpenAI. If they exploited it, attackers could gain full control of servers, stealing or copying anything inside or simply taking sites offline.
The PHP Foundation, the organization that maintains the programming language, had recently learned about the security flaws, but the disclosure was leaked on a forum before a patch could be released. What happened next was a frantic race with numerous participants: the foundation, which needed to create and release a patch; developers around the world, who would need to deploy it; and attackers looking to exploit these vulnerabilities in the interim. Matthew Prince, the CEO of the hosting company Cloudflare, wrote that in the 10 hours before the flaws were publicly announced, “we saw thousands of attempts to exploit it. That jumped to tens of thousands in the 45 minutes post announcement, hundreds of thousands within 2 hours, and millions now.”
Once the patch was released yesterday, websites everywhere went offline to implement the fix. These included government websites in Germany and Finland, some hospital and school websites in Europe, and international sites such as 4chan. During this race to secure the majority of the internet, I noticed one name pop up in posts on Reddit and X: Ondřej Surý.
“Explaining to my wife how there’s this one guy. And he alone is responsible for most of the world’s distribution of PHP,” a software developer named Ian Landsman wrote on X. “And if anything happens to this guy, that’s just it. Everyone is screwed.” He was referring to Surý.
Surý, who lives in Czechia, does not work for the PHP Foundation. But alongside his day job as director of domain-name-system engineering at the nonprofit Internet Systems Consortium, in a volunteer capacity, he maintains and helps automate patches for the coding language. His work, with that of just a handful of others, has allowed countless websites and organizations to fix these vulnerabilities quickly. Over the past 48 hours, he’s become arguably the unsung hero of the entire internet—despite the fact that the only compensation he receives is from modest donations. “Ondřej will save the internet today,” a user in the PHP Subreddit wrote.
I spoke with Surý today from his home about the unfolding AI-cybersecurity crisis, how the internet’s infrastructure is maintained by small crews of volunteers such as himself, and how it feels to go to bed after saving the web as we know it.
Our conversation has been edited for length and clarity.
Charlie Warzel: Explain to me what has happened in layman’s terms over the past 72 hours.
OndřejSurý: Earlier this week, I got notified by the PHP project that there was a serious security vulnerability in the coding. On Tuesday, it became apparent that someone had leaked information about the upcoming vulnerabilities, and it was decided inside the PHP project that it needed to accelerate the release process from Thursday to Wednesday. This is when it became a little bit crazy, because now we were one day short suddenly.
Warzel: I want to try to put this into perspective: So basically, the PHP programming language that kind of undergirds the web is used by up to 70 percent of websites?
Surý: That’s what I heard as well.
Warzel: So people search for cybersecurity vulnerabilities, not necessarily for offensive-attack opportunities but maybe just defensive opportunities. And someone found a vulnerability—that’s not super abnormal. But the real issue here was how widely it was disclosed and the amount of time before people had to patch this, right?
Surý: Let me clarify that: It’s the severity. The severity is unusual. Remote Code Execution is the most severe type of vulnerability, because the attacker is able to execute their own code on the server that’s running PHP. That’s why this caused such panic throughout the internet. As you said, if about 70 percent of websites are running PHP, the impact would be huge if attackers would actually be able to execute code on these servers.
Warzel: You said that despite the panic online, it has not been a crazy 48 hours. From the outside, that’s surprising. I keep seeing people saying, There’s one person who is in charge of fixing this—and he’s supporting himself through Patreon. They may have been exaggerating, but there’s some truth to that: Your work was single-handedly helping millions of people. How could this not be a crazy time for you?
Surý: There are a couple of reasons. One is that I’ve been doing this for a long time, over 20 years. A lot of the stuff that I do is automated. But the reason it was not crazy for me was that I actually don’t have any system running PHP myself. So for me, it was like, sure, I feel a responsibility toward the users of the internet. It would be a crazy day for me if I was on a boat in the middle of the Adriatic Sea. That could happen. But I had time to prepare the packages.
Warzel: That’s kinda wild.
Surý: And even without me, people would still be able to get PHP from other sources and compile it themselves. But it would be more complicated for everyone. And some people don’t immediately have the skill to upgrade the PHP. What the PHP project did was release the source code for the language. What I am doing is preparing it into these things called packages that people can install on their servers. It’s very convenient, and it’s faster, and you can automate it and can install the same package over hundreds and thousands of servers, and you don’t have to compile it. If I was not available, it would take more time; some of them wouldn’t have the skills. Really, the thanks go to the PHP project that invited me into this secret cabal who knew about the vulnerabilities and had access before the public release.
Warzel: When you got invited, was it a real Oh, crap moment for you?
Surý: I’m in the stage of my life where I was like, This is bad. It needs to be fixed. But it doesn’t cause panic, at least for me. It did cause panic for a lot of people. But you know, it was more like, We have a situation, it needs to be solved, and this is how we do it. And I have time to properly prepare. If I didn’t have time to properly prepare, then it would cause a lot of stress. From where I stand, it was not stressful, because I’m doing this as a volunteer, and if I get hit by a bus, then it will be someone else’s problem.
Warzel: Every time I dabble in writing about the world of cybersecurity and open-source software, I discover these groups of maintainers: people such as yourself who do this work because they care. Often, nobody knows their name. But is there a line of people who would take your place if, say, you did get hit by a bus?
Surý: I am actually thinking about contingency plans. And we are talking with Raphaël Hertzog from the software company Freexian. My advantage is that I have a lot of expertise, and I know where to touch the thing to make it work. But Freexian has a lot of expertise, and they would be able to take over if anything happens.
People have been donating small amounts, and larger amounts, like crazy since yesterday. I would like to thank them all.
Warzel: Have the donations been overwhelming?
Surý: Not Silicon Valley levels of money, but I got a serious amount of contributions that I’ve never seen before. It’s like one year of the contributions gathered over the past 24 hours.
Warzel: What would have happened if this wasn’t patched as quickly as it was?
Surý: A lot of things could have happened. The very basic thing is that there would be vandalism, that the sites would be taken down. And we are seeing this every day on the internet now. The other stuff that happens is that someone gets access and runs a botnet out of these devices. I would say it’s mostly organized crime doing that now—it’s not like a small guy in the basement doing this for fun. There are financial incentives for these people to sell the botnet services or to do the crypto-mining on these servers for a profit. And this still could happen, because it’s not like everyone has patched and updated their PHP.
Warzel: I saw a post on X that said not all PHP releases are patched, and one-third of the internet is kind of permanently either broken or vulnerable. Is that correct?
Surý: That initial information is not correct. There are ways to patch even the old versions.
Warzel: So one-third of the internet is not permanently screwed. Okay.
Surý: No, that’s not accurate. If people care enough, they are able to even update these old versions of PHP.
Warzel: It’s a scary moment for cybersecurity. I’ve seen people online referring to this vulnerability and other AI-agent hacks as “Black October,” and there’s concern that defensive or attacking agents can find these vulnerabilities. There is this feeling that I am noticing from the cybersecurity community that their fears of a future where things are being exploited or discovered quicker than people can handle is coming true—that we are living in that moment. And then separately, there’s a contingent of people who are saying there is an equilibrium here: If you have very persistent agents that are very good at identifying and exploiting vulnerabilities, you also have very persistent agents that are very good at defending against them.
Surý: What we’ve seen is that things have accelerated—that’s absolutely right. The defenders are also able to use the large language models to find the vulnerabilities for themselves. I believe it boils down to the simple fact that IT infrastructure is often being taken for granted.
There’s not enough priority and money going to properly maintain the IT infrastructure in various places. It’s not only companies; it’s also a lot of outdated consumer electronics that are going to be attacked. I kind of agree that everything’s moving fast now, and it’s taking a toll on the people who are defending the stuff. At the same time, maybe this is the turning point where we actually start caring about this.
Warzel: Do you feel like that will actually happen?
Surý: I might be wrong, but I’m an optimist that people will finally realize that we can’t go like this forever. This has been a disaster waiting to happen for a really, really long time. And this is just one of the many wake-up calls that came and will be coming.
Warzel: I am amazed by how much the infrastructure in certain areas of the internet can hinge on one or two people. There is a fragility to all of this that is concerning. So what do you want to see?
Surý: When I started doing open-source, it was fun. And it kind of still is. But the environment has shifted. Open-source sometimes feels like exploitation. What I would like to see is to find a new model where people working on open-source would be awarded for their work and the hours and hours they put into it from the people who most benefit from their work. I would like companies to realize that this is exploitation. Any exploitation is not sustainable. And it will end up badly if this continues, because the people doing the open-source will stop being motivated to actually do anything in the end.
Warzel: It sounds like you don’t have an ego about all of this. But you did some work, and you helped out a tremendous amount of people in every corner of the world yesterday. How did it feel to go to bed last night after all of that, knowing the role that you played?
Surý: Well, my wife says that I’m emotionally dead, but I’m not. And it felt nice. Like, seeing my social network filling up with thank-you notes, and getting emails with thank-yous, that feels really nice. It puts some sense into what I do. I felt that what I do has a purpose.
Warzel: The whole internet appreciates your efforts. Is there anything that you would recommend normal people do at this moment to improve their internet hygiene?
Surý: I would recommend that they rely on the experts. That’s what we all do in a crisis: We talk to experts and trust them. Rely on people, that people who take care of this stuff know what they are doing. And that’s all we can do.
From the Fall of the Berlin Wall until about a decade ago my animating intellectual question was pretty much, ‘how did a small number of natural sciences become qualitatively more impressive than the social sciences?’ Because I met the late George Smith relatively early in my thinking about this (as an undergraduate), I often formulated this question in terms of evidence; he liked his version of my question as ‘how to turn data into high-quality evidence?’ And his striking answer was (to simplify) that deviations from theoretically significant expectations through theory-mediated measurement were made informative in an iterative process over time in the sciences that succeeded in achieving lift-off. While I was much more interested in the social organization of the sciences than George, I never did much better than he did in answering my own question. But I did make sure his version was published in the best possible form and with full detail (see his ‘Closing the Loop.’)
Along the way, I became an expert on Newton and his reception and on developments in twentieth century economics, and I found a home in professional philosophy (as a ‘historian of philosophy,’ a ‘philosopher of social science,’ and ‘HPS-type’). At least this is a way one can tell my professional story before I switched (or returned) to political theory. Once in political theory I recognized that Machiavelli’s great contribution to the art of government — that in the right conditions, which includes considerable layers of social opacity, social disorder can itself be informative — anticipates George’s insight into how successive approximation can be fruitful.
Be that as it may, the way professional philosophy is organized, there is no list of ‘open’ questions that are treated as ‘important.’ In fact, there are ways of posing my animating question in terms that made it sound vaguely Popperian (viz. ‘is there a scientific method;’ ‘a logic of discovery?;’ ‘could concepts be stress tested?’)—and so discarded. Sometimes I was directed to others — Alison Wylie, Nancy Cartwright, and Hasok Chang back in the day — whose projects had a family resemblance with my own.
There are some subfields in philosophy where through the force of personality and/or institutional entrenchment (or donor/foundation persistence) some questions do feel significant and open. But more often than not these are treated (after the fact) as evidence of ‘fashion’ in philosophy. Because there is no consensus on what really matters philosophically, and great jobs are scarce in the profession, lots of professional philosophers are in the business of artificially producing prestige (by keeping acceptance rates for the really important journals ridiculously low).
The previous was not really meant to be polemical.
Professional philosophers often think of themselves as constituting a field that’s not very far from professional mathematics. One of our core areas — mathematical logic — even has some overlap with foundational practices in mathematics. And I am just old enough to remember the time when some wise folk thought that having mathematical logicians around in philosophy was a thing thought good, perhaps standards-protecting (even standards-raising), for a department. And I was taught by and mentored for a long time by a philosopher, Jody Azzouni who himself studied mathematical practice, and found that useful in debating what other professional philosophers argued about philosophically important topics.
But judging by the reactions collected at ‘Proofs and Prompts’ to the Open AI math dump last week, the way enquiry is organized in professional mathematics is quite distinct from the relative lack of organization in philosophy. Or to put it differently, professional mathematics has much more of a closed guild structure than we do in philosophy. (Some evidence for this can be gleaned from the way the mathematicians use ‘community’ in ‘mathematical/mathematics community’—no philosopher would speak of our profession as such as a community unless it were in order to be satirical.) There who you study with and what ‘open’ problems you work on have a rather tight connection and, these in turn, have a rather tight connection to one’s professional identity and trajectory. To put it in terms of the economists: barriers to entry and, once in, path-dependent endowment effects are rather steep.
Having a list of such open problems, and an implied sense of their significance to the community, allows for much coordination, including the distribution of honors, jobs, and grant proposals. While there is, undoubtedly, a political economy to the institutions that fund all of this, it has allowed for a non-trivial amount of bottom-up intellectual and collective self-governance as well as exploration. It is, for example, pretty clear that quite a few leading mathematicians have been early adopters of LLMs in their own research and, thereby, have indirectly helped train the next generation of these.
The situation described in the previous paragraph is fairly unique in human history. Few civilizations have invested in pure mathematics to the degree ours has with the rise of the modern research university and dedicated research institutions since (say) the late nineteenth century. (By ‘civilization’ I am happy to be very inclusive.) But by making its official problems explicitly legible (to adopt social science jargon), the ‘mathematical community’ became sitting ducks when the barriers to entry were huge for individual researchers but a relatively easy technological hurdle for a few for-profit corporations with no hard budget constraint (relative to the mathematical community). These companies now control a vital resource that enables one to be on the leading edge of the mathematical frontier. My use of ‘one’ is, of course, a weasel word—because it is wholly unclear if any human can have any leading role on that frontier henceforth.
Perhaps the implied guild structure explains the unseemly schadenfreude with which the demise of professional mathematics has been welcomed by so many commentators. Cheering on the misfortune of those who harm nobody, and who are engaged in a noble activity, is itself evidence of the advanced corruption (recall) of our age.
One sometimes hears from economic historians and sociologists of technology that the technological disruption to the mathematical community, if it is one, is no big deal all things considered. The mathematicians turn out to be no different from the hand-weavers, the loom operators, and the human (mostly female) ‘computers’ that got displaced by machines in the context of progress. But while there is more than a kernel of truth in this (and there is quite a bit of intellectual labor embodied in modern machinery, etc.), this is one of the first times since the rise of the modern research university that a ‘pure’ field risks being overtaken and displaced by one of the (applied) technologies it partially birthed. Philosophers are somewhat used to being told by the practitioners in the fields it helped birth that philosophy is useless and pointless; but it may hit the mathematicians harder. Many mathematicians are in a state of “shock,” “loss,” and depression (as well as anger), but a guild that gets undermined also opens up new opportunities for those impatient or sidelined under the old regime.
As regular readers know (recall here), I argue that the structural (Humphreys) opacity that is inherent in LLMs enhances genuine expertise. But it doesn’t follow from this that the remaining place for human mathematical expertise is on the research frontier of commonly defined open questions. My own scholarly work (with Russo and Wagemans here) suggests that in such conditions there will be more work for certification and less for production. For, opaque systems, when used to produce results, systematically secrete new layers of opacity that need to be checked and monitored.
I increasingly suspect professional mathematics will turn into practiced and idiosyncratic virtuosity, where math slides back into modern art.1 (Danny Calegari’s examples of animations are worth pondering.) Since modern universities find ways to hire, evaluate, and promote all kinds of artists, this may require less administrative adjustment than one might fear.
Of course, if the cutting edge LLMs become more like a utility, then, alternatively, maybe credentialling within mathematics disappears entirely. Automated iterative feedback from deviations then mops it all up.
What about professional philosophy and the scholarship about it (i.e. history of philosophy)? Prestige producers and the journals they control are fighting a rearguard action against the use of LLMs. I expect more and more ‘professional philosophy’ to be co-produced by professional philosophers and LLMs, until we reach the point where LLMs ‘edit,’ referee, and summarize all such papers and are effectively the only ones actually reading them. Given the way it is organized the good news is professional philosophy is not so vulnerable to a hostile takeover; but the bad news is that it is vulnerable to increasing (ahh) hollowing out of its mode of production because that mode is not itself intrinsic to philosophy. (Okay that was polemical.)
That last claim is too strong undoubtedly. Such legibility to outsiders is, of course, a matter of degree and intensity, and one wonders if the philosophical contributions of (say) Jorge Luis Borges will be re-evaluated in light of such considerations (not to mention the fortunes of bits of continental philosophy). By emphasizing Borges here I do not mean to focus on his brilliant thought experiments, but rather on how he indicates new ways of discernment. That means, but this is self-serving, that philosophers will increasingly value and gravitate toward judgment and voice—but I would say that.
Let me rephrase that. You may think that if we take Liam Kofi Bright’s famous distinction between basically pleasant bureaucrats and Sexy Murder Poets seriously, I am predicting the demise of the former and the renewed attraction of the latter within professional philosophy. But while that result would greatly amuse me, it’s not what I am predicting. Rather I am claiming (recall my treatment of synthetic philosophy) that philosophy will rediscover that its vocation is in the tending, nurturing, and monitoring of the machinery of governance of the bureaucratic structure (including the LLMs) that is opaque to society.
1 In some ways this would be a return to Hardy’s perspective, but also with a different conception of art and beauty underwriting it. That is, mathematics will become more like painting in response to the development of photography and the newer digital technologies. (The second half of this footnote was suggested by a token of Opus 5.5.)
It might feel too soon for an update, but so much has changed. The timeline of the post-quantum transition dramatically shifted in early 2026, and there is now consensus that it needs to complete by 2029. 2029! We have three years!
The answers below assume you are not constrained by any specific compliance regime, although they are mostly compatible with FIPS 140.1 If you need to follow something stricter like CNSA 2.0, you’ll know. Just substitute as appropriate.
Finally, remember the other big change of 2026: LLMs are very good at finding bugs now. “Get a review from the best model you can afford” is now firmly a Cryptographic Right Answer, along with the long-time classic “use a memory-safe language.”
If you’re in a rush, here’s the cheat sheet:
Encrypting data: If you’re in the cloud, KMS. Otherwise, XAES-256-GCM or XChaCha20Poly1305 with random nonces. If you’re encrypting more than a few MB, use Cobblestone-128.
Symmetric key length: Don’t stress it. 256-bit keys if you need to pick.
Symmetric “signatures”: HMAC-SHA-256.
Hash algorithm: SHA-2 is still fine, but use a real multihash (SequenceHash) if needed.
Random IDs: 32 random bytes, a.k.a. 256-bit random numbers.
Password handling: Argon2id or scrypt. But have you considered passkeys instead?
Key exchange: X25519+ML-KEM-768 in a secure, standard protocol.
Asymmetric encryption: HPKE with (MLKEM768-X25519 a.k.a. X-Wing, HKDF-SHA256, AES-128-GCM), or age with PQ keys.
Asymmetric signatures: ML-DSA-44.
Website or client-server application security: If you’re in the cloud, use its ALB/NLB. Otherwise, rustls, Go’s crypto/tls, BoringSSL, AWS-LC, or s2n-tls with a popular, updated ACME client.
Online backups: restic with a long random password.
Now let’s dive in.
Encrypting data
If you’re in the cloud, KMS. Otherwise, XAES-256-GCM or XChaCha20Poly1305 with random nonces. If you’re encrypting more than a few MB, use Cobblestone-128.
Percival, 2009: AES-CTR with HMAC. Ptacek, 2015: NaCl/libsodium default, or ChaCha20Poly1305, or AES-GCM. Latacora, 2018: KMS, or XSalsa20+Poly1305. Latacora, 2024: KMS, or NaCl’s secretbox, or XChaCha20Poly1305.
If you’re encrypting locally, you want an AEAD where you can avoid worrying about tracking nonces or how many messages you encrypted, so you want random nonces of at least 128 bits.2
NaCl/libsodium’s secretbox is just a paper-thin wrapper around a less common AE construction (XSalsa20+Poly1305), so instead I recommend XAES-256-GCM or XChaCha20Poly1305. The former is an efficient composition of a standard KDF and AES-GCM, packaged as an extended-nonce AEAD, so even if your library doesn’t provide it under that name you can assemble it from the KDF and AES-GCM APIs.3
Regular AES-GCM and ChaCha20Poly1305 with random nonces are only ok if you know for certain you won’t encrypt more than a billion messages with one key. AES-GCM-SIV is also a good AEAD choice if you happen to have it everywhere you need it, but that’s kinda unlikely. Some even newer options have nice properties like key commitment, but are not commonly available yet.
Since you have an AEAD, consider putting context in the additional data, like the user ID you’re encrypting for, or the version of the protocol. Anything not secret that you will definitely still know at decrypt time.
Very important is how you handle large messages, which KMS will not solve for you. Do not pass one large message to an AEAD, or you might be forced to process or store the plaintext before having authenticated it at decrypt time. Absolutely do not use unauthenticated stream ciphers. Instead, you should use STREAM (which is not a stream cipher but a way to use AEADs on a stream… I know, I know, terrible name). There are a lot of options—too many, in fact—and shamefully none are the consensus answer. Tink has one, libsodium has one, the AWS Encryption SDK has one, FLOE is one, age has one, and the list goes on. I recommend Cobblestone-128, which is a STREAM variant derived from TLS, and is available in pyca/cryptography and soon in the Go standard library (and in the meantime at filippo.io/cobblestone).4
Avoid: unauthenticated modes (CBC, CTR, raw stream ciphers), random 96-bit nonces unless you spent a lot of time thinking about how many messages you encrypt, rolling your own AEAD construction.
Symmetric key length
Don’t stress it. 256-bit keys if you need to pick.
Remember that Grover doesn’t actually matter and 128-bit brute-force attacks don’t exist. Still, 256-bit keys rule out multi-target attacks, which is nice.
However, don’t make other decisions based on this. For example, the recommended Cobblestone suite uses 128-bit keys and that’s fine because it has a careful analysis of multi-target attacks. Likewise, don’t go changing the default cipher suite preferences of your TLS library to enforce 256-bit keys; there’s no need.
AES-256 is slower than AES-128 because unfortunately Rijndael ties the number of rounds to the key size, but this probably won’t matter in practice.
Avoid: anything other than 128 or 256 bits, worrying too much about size, keys that are not uniform (e.g. using a password or ASCII hex string directly as a key).
Just be careful to sidestep canonicalization and parser alignment bugs by always authenticating a verbatim string of bytes, not something you need to recompute.
You can use KMAC or keyed BLAKE3 if you already had a reason to use their underlying hashes. HMAC-SHA-512 is also fine.
Remember to compare tags with dedicated constant-time functions.
Avoid: rolling your own YoloMAC, encrypted hashes, standalone one-time MACs like Poly1305 or GMAC.
Hash algorithm
SHA-2 is still fine, but use a real multihash if needed.
Percival, 2009: SHA-256 (SHA-2), plan on SHA-3. Ptacek, 2015: SHA-2. Latacora, 2018: SHA-2. Latacora, 2024: SHA-2.
The best option, if you have it available, is still SHA-512/256, which isn’t vulnerable to length-extension attacks. Otherwise, SHA-256 and SHA-512 are both fine.5
SHA-3 is unnecessary (because SHA-2 is fine) and slow,6 but not wrong. If you already have Keccak (SHA-3) around for ML-KEM and ML-DSA, and you want to use it for hashing, draw 32 bytes from SHAKE128.
BLAKE2 is a weird choice these days. BLAKE3 is very fast, but complex and uncommon enough that you want to have a good reason to use it and a good reason to trust your implementation.
Multihashing is when you need to hash multiple things at once. For example, multiple columns of a row, or a filename along with the file contents. It’s subtler than it sounds, so use SequenceHash with SHA-2, or TupleHash (SP 800-185) with SHA-3.
Avoid: SHA-1, MD5, all other hash functions, rolling your own multihash, truncating to less than 256 bits unless a cryptographer told you collisions are not a concern.
Random IDs
32 random bytes, a.k.a. 256-bit random numbers.
Percival, 2009: 256-bit random numbers. Ptacek, 2015: 256-bit random numbers. Latacora, 2018: 256-bit random numbers. Latacora, 2024: 256-bit random numbers.
Note that UUIDv4 and APIs like rand.Text will give you ~128-bit values instead. That’s usually fine, unless you need more than 280 trillion (2⁴⁸) unique values. 256 bits is overkill, but why not.
Use your operating system’s CSPRNG: getrandom on Linux, ProcessPrng on Windows, arc4random_buf on macOS and BSD, getRandomValues on the web. A good library will wrap these for you.
Avoid: non-cryptographic PRNGs, userspace random number generators like OpenSSL’s, haveged, CPU jitter entropy.7
Password handling
Argon2id or scrypt. But have you considered passkeys instead?
Percival, 2009: scrypt or PBKDF2. Ptacek, 2015: scrypt, then bcrypt, then PBKDF2 if you must. Latacora, 2018: scrypt, then Argon2, then bcrypt, then PBKDF2 if you must. Latacora, 2024: Argon2id, then scrypt, then bcrypt, then PBKDF2 if you must.
Everything my predecessors said is still spot on: “you can throw a dart at a wall to pick one of these.” I dropped bcrypt because the 72-byte truncation bites. One tip: you could argue to your auditors that scrypt is FIPS 140 compliant because its actual KDF step is PBKDF2, which is what they want. I heard it works.
For parameters, ignore RFC 9106 which apparently wants to murder your production system, and use m=64 MiB, t=2, p=1 for Argon2id (libsodium’s INTERACTIVE preset) or N=2^16, r=8, p=1 for scrypt. They use the same memory, but the scrypt ones will take ~1.5× the CPU time and ¼ the GPU time, which is why you should prefer Argon2id. If you’re doing non-interactive key derivation, feel free to crank up Argon2id’s m, and then t (or just N8 for scrypt) as far as tolerable.
Much more importantly, do you really need passwords? If you only need them for logins, could you use phishing-proof passkeys instead? Maybe with email magic links as a fallback? Or just support SSO (as long as it’s OIDC and not SAML)?
(Note that in 2026, passkeys are still not PQ. That’s mostly fine. They’re still phishing-proof and credential-stuffing-proof. All a quantum attacker can do is log in to a specific site if they obtain its database or intercept a login.)
Avoid: regular hashes, spending time thinking about password hashes instead of focusing on passkeys, phishable variants of email-based logins.9
Key exchange
X25519+ML-KEM-768 in a secure, standard protocol.
Percival, 2009: 2048-bit Group #14 with a generator of 2. Ptacek, 2015: Probably still DH-2048, or NaCl. Latacora, 2018: Probably nothing. Or Curve25519. Latacora, 2024: X25519+ML-KEM-768.
The 2018 version of the Latacora answers is correct in asking “why are you as a developer thinking about this, and what does it even mean?!” Don’t roll your own key exchange protocol. Just pick X25519MLKEM768 in TLS, mlkem768x25519-sha256 in SSH, and/or MLKEM768-X25519 in HPKE and age. If you really need to obtain some keys and you know what you’re doing, both TLS and HPKE have “exporters” to derive them.
Non-PQ solutions are an active, urgent liability due to harvest-now-decrypt-later attacks, and PQ alternatives range from impractical (HQC-KEM, FrodoKEM) to impractical and broken (Classic McEliece).
For key exchange, using an ECC hybrid is cheap enough to be worth it, and indeed ML-KEM is usually deployed alongside ECDH. However, if picking or implementing the hybrid is going to make you stay even a single month longer on a classical, non-PQ key exchange, go straight to pure ML-KEM-768 now.
P-256+ML-KEM-768 is also fine, just less common. NIST P curves got a bad rep for many years, but I think it’s 90% because they came out before we knew how to do cryptography engineering particularly well (and because of… let’s say non-NPOV proselytizing). Almost none of the attacks against ECDH on NIST P curves even matter for ephemeral key exchanges.
Avoid: anything and everything without ML-KEM or X-Wing (a specific X25519+ML-KEM-768 combiner) in its name.
Asymmetric encryption
HPKE with (MLKEM768-X25519 a.k.a. X-Wing, HKDF-SHA256, AES-128-GCM), or age with PQ keys.
Percival, 2009: RSAES-OAEP with SHA-256, MGF1+SHA-256, and exponent 65537. Ptacek, 2015: NaCl. Latacora, 2018: NaCl/libsodium (box / crypto_box). Latacora, 2024: Tricky, wait for established PQ solutions.
This is one of the most improved answers in recent years, as we now have a standard to do hybrid encryption: HPKE. (“Hybrid” as in asymmetric + symmetric, not as in classical + post-quantum, yay for overloaded names.)
MLKEM768-P256 is also ok as a choice of KEM, but less available. Pure ML-KEM-768 is fine if it’s all you have. All KDF and AEAD choices are fine, as well.
If your message is large, do the same chunking Cobblestone does, with multiple sequential HPKE Seal/Open calls in place of the AEAD.
Note that the PQ HPKE KEMs are maddeningly still a draft.10 Worse, they are unnecessarily spread over four drafts, such that I had to write filippo.io/hpke-pq. However, I made the authors solemnly swear they will not change the wire format, and then we all shipped them in our cryptographic libraries, so you can and should use them.
If you need something higher-level, with multiple recipients or a CLI, use age11 with its new age1pq-prefixed keys, based on MLKEM768-X25519. PQ support is also rolling out for plugins like the YubiKey and the Secure Enclave ones.
Avoid: again anything not based on ML-KEM (RSA and NaCl’s box12 in particular), OpenPGP, encrypting emails.
Asymmetric signatures
ML-DSA-44.
Percival, 2009: RSASSA-PSS with SHA-256, MGF1+SHA-256, and exponent 65537. Ptacek, 2015: NaCl, Ed25519, or RFC 6979. Latacora, 2018: NaCl or Ed25519. Latacora, 2024: Ed25519 if short-lived, otherwise Ed25519+ML-DSA-65.
Just use ML-DSA-44. If your message needs pre-hashing, use “external-μ (Mu)” signing, not HashML-DSA. Store keys as 32-byte seeds exclusively.
The two PQ alternatives are FN-DSA, which is stuck somewhere in the US Department of Commerce, and SLH-DSA, which is based on hash functions. The latter can make sense for some specialist use cases, but is slow, large, and not widely available in implementations.
Why not a hybrid or “composites”? Hybrid auth is more complex and less useful than hybrid key exchange. I need to write a long-form post about this, but in short either you already have a key rotation strategy that you can use to rotate back to RSA/ECDSA/Ed25519 in the unlikely case of a cryptanalytic break, or you have such a long time horizon that you should assume quantum computers will break the classical half anyway.
Also, ML-DSA is just such a better signature algorithm than its predecessors. It has hedged randomness (which is better than both random and deterministic nonces), built-in context, extra properties like SUF-CMA, and is relatively simple to implement and test.
Why the -44 parameter set, when I’m recommending ML-KEM-768? Unlike ML-KEM-512 (NIST category 1), ML-DSA-44 sits at NIST category 2, with some margin above the 128-bit security level already.
The one exception to the no-composites rule is SSH keys. OpenSSH 10.6 picked ssh-mldsa44-ed25519. I think they made a mistake, but it would be a mistake for you to go off the beaten path there.
Note that asymmetric signatures are overused, and especially now that they are not cheap, you should try to avoid them. Consider whether you could use a simple HMAC. Maybe you can replace signed JWTs with random session tokens. If instead you do want to commit to something publicly, consider whether you should use a transparency log, and get a more practically useful notion of non-repudiability (and potentially smaller sizes, if you amortize the signature over multiple proofs).
Avoid: all non-PQ options like RSA/ECDSA/Ed25519, stateful signatures (LMS/XMSS), HashML-DSA, ML-DSA “semi-expanded keys,” composite signatures, OpenPGP.
Website or client-server application security
If you’re in the cloud, use its ALB/NLB. Otherwise, rustls, Go’s crypto/tls, BoringSSL, AWS-LC, or s2n-tls with a popular, updated ACME client.
Percival, 2009: OpenSSL for websites, custom RSA protocol for applications. Ptacek, 2015: OpenSSL, or BoringSSL if you can. Or just AWS ELBs. Latacora, 2018: AWS ALB/ELB or OpenSSL, with Let’s Encrypt. Latacora, 2024: AWS ALB/ELB or OpenSSL, with Let’s Encrypt.
Not recommending OpenSSL will probably be my least practical suggestion, but OpenSSL has been making consistently puzzling and problematic choices for years now. The pyca/cryptography authors, in a long post about OpenSSL’s issues, summarize it as:
Our experience with OpenSSL has been on a negative trajectory for several years.
I recommend rustls or Go’s crypto/tls,13 which are memory safe. If you need to stick to C, both BoringSSL and AWS-LC are very competently maintained OpenSSL forks, and the latter, unlike BoringSSL, has versioned releases. s2n-tls and rustls-ffi are interesting options if you don’t need libssl compatibility.
Whatever you use, make sure it prioritizes the X25519MLKEM768 key exchange, which requires TLS 1.3. Your cloud load balancer might require you to select a PQ security policy. On RHEL 9 and derivatives, you need to opt in.
Previous lists split websites and client-server applications. I merged them because these days you’ll just use the same TLS stack for both. What changes is the PKI. For applications where you control both ends, consider making your own ML-DSA-44 X.509 certificates, self-signed or from a private root. For websites, wire up a popular, well-supported ACME client and keep it up to date. Merkle Tree Certificates will roll out in 2027, and you want to be well positioned to be included in the transition.
Avoid: rolling your own transport protocol, TLS libraries that failed at their core job before (GnuTLS14, Mbed TLS151617, wolfSSL1819202122232425, Botan2627), offbeat TLS libraries, OpenSSL before version 3.5 (the first with X25519MLKEM768), any OpenSSL if you can, TLS 1.0–1.1, TLS 1.2 if you can, rolling your own ACME client.
We all love Tarsnap, and I feel like I am betraying my elders right now… but its asymmetric cryptography layer is all RSA. Technically, I think the only things that truly break are the lower-capability keys: a write-only key can decrypt archives and a read-only key can forge archives. Server authentication is HMAC, and the RSA public keys are never sent to the server. In that sense, Tarsnap is as secure as restic, which is an impressive feat for a 2008 design. However, this feels like a major footgun with impending quantum computers.
The picture
Kinda incredible that you can just walk up to this thing.
FIPS 140 still has some very ugly bits around module validation (runtime self-tests, the integrity check, and the worsening RNG mess) but the actual cryptography algorithms these days are “good, actually.” ↩
You might read that GCM can take 128-bit nonces, but when you do that it doesn’t have a separate CTR counter anymore, and messages with different GCM nonces can end up sharing CTR keystream, which makes the analysis more complicated. ↩
Again, full disclosure, this is my design, but it’s adopted externally enough that I feel comfortable recommending it. ↩
On 64-bit machines, SHA-512/256 and SHA-512 should be faster than SHA-256 thanks to their larger block size, except right now hardware support for SHA-256 is more widespread, so SHA-256 is faster in practice. They are both fast, so you probably don’t care. ↩
Partially because of choices NIST made to make SHA3-256 strictly as secure as SHA-256, even where SHA-256 was overkill. SHA-256 and SHA3-256 have 128 bits of collision resistance and 256 bits of second preimage resistance. It’d be enough to have 128 bits of both, which is what you get from 256 bits of SHAKE128 output. Unfortunately, it doesn’t have a SHA name. TurboSHAKE128 (RFC 9861) would be even better, but it is neither FIPS 140 nor widespread. ↩
People outside the FIPS 140 circle of hell don’t seem to have noticed, but new NIST rules require FIPS 140 modules to have an “internal” entropy source now. If your FIPS 140 “module” is a piece of software… what do you do? Everyone’s answer is “CPU jitter”: run a tight loop that accesses uncached memory and take high-resolution timestamps, hoping the frequency mismatch between CPU and main memory will make the measurements unpredictable. IMHO, this is the worst part of FIPS 140 since the module integrity hash, and it will hurt people. The one sane way to do it is to go through the motions, and then at the last moment mix the result with kernel entropy, like Go does. However, that’s harder to justify to the validation labs than doing just CPU jitter, so I’m afraid we’ll see pure CPU jitter in production a lot. ↩
A link with an opaque random token that logs in the opening browser is very hard to phish. A link that logs in the browser that started the login is very easy to phish. Short numeric codes are moderately easy to phish. (You can get the best of both worlds by using the Broadcast Channel API to pass the token from the new tab to the original one.) ↩
In a different venue I said a serious engineering community would have a post-mortem about having wasted two of the five years we had for the transition to post-quantum cryptography, only to produce specs that changed nothing compared to what we had in 2024. But that’s for another time. ↩
Again again, full disclosure: my design, but pretty uncontroversial pick. ↩
I truly don’t understand why my predecessors recommended NaCl’s box. It’s an incredibly sharp and low-level API, pretending to be a high-level safe API. ↩
One last time, full disclosure: I am a crypto/tls maintainer. ↩
CVE-2020-13777, GnuTLS 3.6.4–3.6.13: the session ticket key is all zeroes, breaking confidentiality in TLS 1.2 and allowing authentication bypass in TLS 1.3. ↩
CVE-2023-45199, Mbed TLS 3.2–3.4: pre-auth remote code execution via an oversized key share in the TLS 1.3 handshake. ↩
CVE-2026-25835, Mbed TLS 2.18.0–3.6.5 and 4.0.0: the RNG state is cloned across fork, so parent and child produce the same random values. ↩
CVE-2026-5194, wolfSSL 3.12.0–5.9.0: signatures by ECDSA certificates can be forged by providing an ML-DSA or Ed25519 signature algorithm identifier and a trivial ECDSA signature over the zero-length digest. ↩
CVE-2026-5501, wolfSSL through 5.9.0: the OpenSSL compatibility layer skips the leaf’s signature check when any valid end-entity cert is supplied as an “intermediate.” ↩
CVE-2026-11310, wolfSSL 5.8.4–5.9.1: the OpenSSL compatibility layer lets caller-supplied untrusted intermediates act as trust anchors. ↩
CVE-2026-11999, wolfSSL 5.7.4–5.9.1: the OpenSSL compatibility layer accepts any chain longer than the maximum path depth of 100, without reaching a trust anchor. ↩
CVE-2026-55960, wolfSSL 5.6.4–5.9.1: a raw public key is always accepted in place of a certificate, bypassing authentication. ↩
CVE-2026-93302, wolfSSL 5.3.0–5.9.2: trusted-peer certificates are matched by name rather than public key. ↩
CVE-2026-89136, wolfSSL 5.6.0–5.9.2: clients still accept an unsolicited raw public key from the server, bypassing authentication. ↩
CVE-2026-89135, wolfSSL 5.8.4–5.9.2: a failed chain verification in the OpenSSL compatibility layer permanently adds the attacker’s CA to the trust store used by native TLS, OCSP, and CRL checks. ↩
CVE-2026-34580, Botan 3.11.0: an end-entity certificate whose DN matches a trusted root is accepted as if it were that root. ↩
CVE-2026-34582, Botan before 3.11.1: TLS 1.3 servers process application data before Finished, so a client can skip Certificate, CertificateVerify, and Finished entirely, a full client authentication bypass. ↩
Updates (Oct. 9): To address some questions that keep coming up…
No, I’m not aware of any direct practical implications of any of these results. I certainly don’t expect the O(n log0.9999999999999 n)-time Fourier Transform algorithm to get practically deployed anytime soon! But anyone who harps on this, simply doesn’t understand what mathematical progress looks like, or how it eventually pulls the rest of science and technology and human civilization with it. If and when the relevant human mathematicians understood the clever new ideas in all 372 of these papers, I have no doubt that they’d be able to use the ideas to do all sorts of new things, and that some of those things would have practical value. That’s yet another reason to try to keep human understanding at the center of our enterprise—unless, of course, you’re happy to outsource the task of understanding and applying the ideas to AI models as well.
Meanwhile, something calling itself the Association for Human Mathematics put out a statement condemning OpenAI for its release. The statement included a sentence that’s since been widely mocked on social media: “Mathematicians did not ask for this work to be done.” (Imagine G. H. Hardy saying to Ramanujan, “who asked you to prove all these bizarre new identities?”)
If it wasn’t clear, the members of AHM speak for themselves, not for the math community as a whole. For my part, I think the math and CS theory communities should absolutely hold the AI companies’ feet to the fire to behave better, both within our little domains, and (much more consequentially) in pacing AI progress, figuring out alignment, and preventing a catastrophe for our whole civilization. So I’m glad that our communities have increasingly been doing that, and I hope to have played a tiny part.
At the same time, I regard the position “no one should spoil our fun by solving our open math problems using AI models” to be totally untenable. It offers no argument for why refraining would be in the broader public interest—as opposed to various mathematicians’ narrow career interests. It violates the core principle that math problems are there for absolutely anyone (yes, even a hated corporation) to try to solve. And of course, it’s not enforceable anyway, in a world where these capabilities will rapidly diffuse to anyone with a GPT or Claude subscription.
We will need to adapt to this new world.
… then they came for Navier–Stokes and I said nothing because I never worked on Navier–Stokes. But when they came for RL vs. L I realized that things are serious
–friend-of-the-blog Omer Reingold (shared with permission)
Last night my 9-year-old son was taunting my wife, complexity theorist Dana Moshkovitz, as follows: “mommy, I heard you got cooked! I heard that a robot solved the math problem you worked on for your whole career! OOF!”
While my son was being a brat, he also wasn’t wrong. Whether you’re thrilled, depressed, angry, or whatever else about it, yesterday was surely one of the biggest days in mathematical history. And yes, among the 372 huge results released yesterday by OpenAI, on the recommendation of its advisory group of Timothy Gowers, Edward Witten, and other distinguished mathematicians, was a proof of Subhash Khot’s Unique Games Conjecture (UGC), a statement that my wife has worked toward proving for the entire time I’ve known her. (The UGC implies that a whole slew of optimization problems really are NP-hard, even if you just want an approximation that’s slightly better than what you get from semidefinite programming relaxation, which is one of our main tools.)
Or at least, we’re pretty sure that it’s a proof! There’s a Lean certificate, as there are for some of the other 372 breakthrough results (not all of them). But it also appears that no human has understood just about any of these proofs yet; the race to do so has just started. If you want an on-the-ground sense of what that race is going to be like, here’s some of what Dana texted me last night:
It feels like something written by someone who’s on psychedelics. So much unclear and doesn’t make sense. Lots of name dropping of previous work without discussing why it can be used despite impossibility results
Basically the paper is so horribly written that it’s impossible to read it without AI help
I asked Astra for reasonable completeness and soundness claims of the noise gadget and it gave them by combining claims from all over the paper
They also have direct optimal NP hardness of approximation proofs for the main applications of the UGC (Max Cut and all CSP) that bypass the UGC.
The UGC proof invents a completely new bizarre code with a noise test. It’s some crazy recursive construction.
It’s not the long code, not the short code – some alien craziness
I still think that there maybe is a proof that uses the half space code (which is natural)
The citations are often irrelevant and confusing
A possible future is a math world that’s heavenly if you have vision/creative ideas that AI could help check and implement.
And of course there’s a lot for us to learn from the aliens
If you’re wondering what emotions Dana is feeling—well, probably all of them! Even while a central career aspiration has fallen to a robot, there are at least two mitigating factors for her. First, she can feel vindicated that the UGC was true after all, something she never doubted even while many of her colleagues did! Second, all of us in math and theoretical computer science and mathematical physics, at least those who cared about solving crisply-stated problems, are now in the same boat.
Besides the Unique Games Conjecture, here’s a small sampling of the treasures from Aladdin’s cave that I’ll probably be paying the most attention to over the coming weeks:
L=BPL (i.e., probabilistic logspace and deterministic logspace are the same thing), one of the great derandomization conjectures short of P=BPP. Though its truth was never in serious doubt, there was a whole subcommunity focused on proving this.
The Fourier Transform and integer multiplication in less than O(n log n) time, breaking a barrier that had stood since the 1960s. The new running time, if you’re curious, is O(n log0.9999999999999 n), give or take some 9’s.
Positive solution to the Unitary Synthesis Problem, which Greg Kuperberg and I posed back in 2007. For every n-qubit unitary transformation U, there exists a classical oracle A such that U can be implemented in quantum polynomial time with access to A. This is the opposite of what most of us expected, and could have implications for e.g. the computational problem of decoding Hawking radiation from a black hole and many other problems in quantum complexity theory—if we had an efficient way to construct the oracle A, which this paper doesn’t give. (Added:Here’s a beautiful blog post by friend and colleague Dakshita Khurana about the years she spent working on this problem—unlike me and most others, she believed correctly in a positive answer to it—and her current feelings as she works through the AI’s proof.)
Parity is not in QAC0, one of the great questions of quantum complexity theory since 1999 that many of my colleagues had been closing in on.
Uncomputability of solving polynomial equations over the rational numbers—this was arguably the biggest open problem in computability theory (note that uncomputability of solving Diophantine equations, i.e. polynomial equations over the integers, was proved in the 1970s, giving a negative answer to Hilbert’s 10th Problem)
Any of the above, alone, could easily have been “result of the year” in some area (and in some cases, like Unique Games and L=BPL, in all of CS theory). And there’s a lot that I’ve left out—feel free to share in the comments whatever is making your eyes bug out! There are equally astounding wonders in number theory, combinatorics, algebraic geometry, analysis, and pretty much every other area of math, most of which I’ll never understand, although I’ll note that it includes partial progress toward the Riemann hypothesis and the Hodge Conjecture and the Birch-Swinnerton-Dyer Conjecture (i.e., the majority of the remaining Millennium Problems).
We can take solace in what’s missing from the list. P≠NP isn’t there, nor even P=BPP or NEXP⊄P/poly, and surely not for lack of trying. Apparently the greatest open problems of theoretical computer science are indeed pretty hard!
Oh, lest I forget: one day before the OpenAI dump, meaning Monday evening, Virginia Williams and Josh Alman posted an arXiv preprint that solves the 3SUM problem in O(n1.9992) time, and the All-Pairs Shortest Paths problem in O(n2.9995) time, refuting half-century-old conjectures that the correct answers were n2-o(1) and n3-o(1) respectively. In this case, it wasn’t an OpenAI model that supplied the crucial idea; it was an Anthropic one! But Anthropic then took a different approach from OpenAI: rather than post the undigested solutions to the world, it gave Virginia and Josh the opportunity to write and announce a digested version in exchange for compensation.
These have emerged as the two main models for communicating AI math breakthroughs, and they both have strengths and weaknesses. The “OpenAI model” sets up a crazy race among humans to digest and explain a messy AI proof (work that could easily be some combination of thankless, barely-credited, competitive, and unfun), while the “Anthropic model” puts a private company in the position of picking and choosing which human mathematicians get to be the emissaries of the AI. Dunno, what do you guys think?
For those who are wondering: apparently, the AI model that produced all these wonders was not bespoke contraption of 10,000 agents burning millions of dollars worth of compute, as was used for example to construct a finite-time blowup for the Navier-Stokes equations. Instead, it was simply the latest internal OpenAI model—one that might be released to paying ChatGPT customers within the next couple of months, depending on the recommendations of OpenAI’s safety board! (My 9-year-old son: “Oh they definitely shouldn’t release that. If it could solve all those math problems, it can’t possibly be safe.”) Apparently they used about 3 hours of GPT-Pro level compute on average per problem solved.
Also, if you were wondering: apparently they tried the model on about 8,000 problems. So, right now it “merely” solves ~5% of the longstanding open mathematical problems that it’s asked about, the problems that whole communities have spent years on, after a single 3-hour attempt on them.
I’ve been glad to see the CS theory community rising to the occasion. At the Simons Institute in Berkeley, here at UT Austin, and elsewhere, I’ve hearing stories of researchers rushing to pore over the manuscripts and make sense of them and explain them—because what else do we do? How else do we continue the craft to which we’ve devoted much of our lives?
If you want some sense of what things feel like now in math, imagine a hunter-gatherer who’s spent his entire life learning to survive deep in an unforgiving rainforest, then a giant resort hotel springs up right next to him with a helipad and heated pools and AirBnBs, and without missing a beat, the hunter-gatherer says: “alright fine, so now my new job is to run wilderness retreats for the tourists, or something.”
It’s as if you were teleported to the peak of a tall mountain. Surrounded by fog, you have no idea where you are, or what’s around you. You do not know how your mountain connects to others, and you have no equipment to help you explore, no way to help someone else join you. If you had climbed the mountain yourself, you would have experienced how the human body adapts to altitude and changes in oxygen levels. You might have had to invent tools to navigate, to climb steep cliffs, or to make a shelter. You might have encountered a fellow explorer, gotten lost together in a hidden valley, and found a plant that could be turned into a life-saving medicine.
Instead you’re perched on the peak but in the dark, while the maker of the teleportation machine tells you that it can explore the wilderness better than any human.
For any one of these mountains, if we care enough, I feel optimistic that we can do as we always have: clear the fog and figure out the path, except now using the teleportation machine to help guide us. The bigger challenge will be to nurture a community that still cares about the heroic adventure of finding the paths up these mountains in the world with the machine. (Oh, and I think one place where the metaphor breaks is that we still do have each other, as much as we ever did before!)
Experience has shown that, even now, there will still be people explaining in patronizing tones why none of this is real and none of it counts. If such people were capable of being impressed by anything that happens in the empirical world, of updating on anything, they would’ve already been impressed and already updated several years ago, long before things had reached the point of an actual Mathocalypse.
So, they’ll say, maybe the alleged solutions are not solutions at all, but just “AI slop.” Or maybe none of the 372 well-known open problems that were solved were real math problems, they were all just glorified contest puzzles and trivialities. (After all, there’s still no Riemann Hypothesis!) Or maybe the entire 4000-year-old discipline of mathematics needs to be jettisoned: turns out that it was all just puzzle-solving and trivialities; all that’s different is that now the triviality stands unmasked. In any case, what really matters is that the true inner sanctum of human creativity hasn’t been breached and probably never will be, and also, that Sam Altman and Dario Amodei are contemptible little nerds.
If you’re still a proponent of that doomed worldview, still aboard the sinking ship, I encourage you in the strongest possible terms to read yesterday’s other great contribution to AI discourse, besides the OpenAI Mathocalypse dump: namely, Scott Alexander’s open letter to Steven Pinker. I feel some responsibility for this, as the person who first introduced Steven Pinker to the existence of the rationalist community, and who also first introduced Steven Pinker and Scott Alexander to one another (they had both been fans of each other’s writing). And now Scott is challenging Steve to a literal duel, with guns!
For whatever it’s worth: Steve is a lifelong intellectual hero of mine, just as he is for Scott, and I also have to privilege of calling Steve my friend. But I found Scott’s post to be one of the most devastating rejoinders to anything that I’ve ever read. And I thought Scott’s conclusion was exactly right: when it comes to AI risk, Steve’s great challenge is now to accept and start using a more “Pinkerite” epistemology.
Last night, while I should’ve been poring over some of OpenAI’s hundreds of papers and/or writing this post, I decided to spend some time with my kids instead. They wanted a movie night, so I suggested something they’d never seen before (and that I hadn’t seen for decades), and that seemed chock-full of no-nonsense, practical guidance for the world in which they’re going to grow up: Terminator 2.
Update: As several people have pointed out, cryptography is a subfield that’s extremely conspicuous by its absence from OpenAI’s list of 376 papers! But my sources tell me that the AI companies have now started, gingerly and discreetly, investigating whether their latest internal models can break important cryptographic protocols and primitives. If they can, then it would certainly be nice to get ahead of things before the rest of the world figures out the same.
Another Update: The statement put out the Advisory Group on Mathematics and Artificial Intelligence is very carefully phrased, neither endorsing nor condemning what OpenAI did, and is worth a read:
As announced a few weeks ago, OpenAI has released a large collection of mathematical results generated by an internal model, reporting solutions to hundreds of open questions. This is an important event for mathematics, with consequences both for mathematics and for the mathematical community that extend far beyond the individual results.
AGMAI’s advisory role should not be interpreted as a judgment of the impact of these results or an endorsement of the process by which OpenAI obtained them. We do not speak on behalf of the entire mathematical community, and only the mathematical community can undertake the assessment that is needed.
Making this work public is a first step. This release is the beginning, not the completion, of the process of human understanding and the incorporation of the work into mathematical knowledge. At the same time, the future of mathematical research cannot consist only of understanding results produced by AI labs. Mathematicians must be able to formulate their own questions, develop their own approaches, and explore directions that have not been selected as examples of an AI system’s capabilities. Equitable access to powerful research tools and adequate computational resources are essential to that freedom.
We reaffirm our published recommendations on responsible release. We have discussed them with OpenAI and appreciate the company’s willingness to engage. While we consider these discussions constructive, it is ultimately up to the mathematical community to assess the extent to which our recommendations were followed successfully, and whether there are others we should suggest. We remain committed to engaging with any frontier AI lab on these questions and have already been in contact with several of them.
The Museo de Historia de la Computación in Spain has unveiled a 1:1 scale visual replica of the famous Cray-1 supercomputer from 1976. Instead of sourcing expensive, cutting-edge tech to run the system, the creative team powered the project with 30 2012-era Mac Minis. Developed over 18 months, the project serves as a 50th-anniversary tribute to the Cray-1 and Apple's founding.
Mac Minis from over a decade ago might not seem like the obvious first choice for building a cluster supercomputer, but when networked together, the developers can orchestrate the 64 active processing cores into a combined 1.3 teraflops of performance in their most recent tests. The museum reportedly achieved 1.5 teraflops previously using all 70 available cores, prior to one node going offline. Benchmarks were obtained using a custom matrix-multiplication Python script. Five PCs are quad-core i7s, and the remaining 25 are dual-core i5 models. Except for two units from 2014, the rest of the array dates to 2012.
The replica is a valuable tool for museum-goers to understand the shifts in computer architecture since 1976. The original Cray-1 used vector processing, applying a single instruction to multiple data elements simultaneously, whereas the replica distributes work across independent processors in a parallel cluster. The peak theoretical performance of the original Cray-1 was approximately 160 megaflops. What was originally a purpose-built research machine has been re-created with consumer hardware that's vastly more capable than the machine that inspired it.
Rather than opting for a more standard Linux distribution, the team found that macOS Mojave (10.14) met their project needs by harnessing macOS's built-in support for MPI (Message Passing Interface), the software layer that allows all the nodes in the cluster to pass tasks to one another.
The Cray-1 replica, complete with iconic padded bench seating. The only thing missing is Robert Redford and Ben Kingsley having a discussion on SECTEC Astronomy. Credit: Museo de Historia de la Computación
Credit:
Museo de Historia de la Computación
Guests at the Museo de Historia de la Computación can watch in real time as the system runs matrix algorithms, mapping the scale of system performance from a single core to the full suite running in parallel.
Stealth supercomputing
Combining 30 consumer PCs into an operational cluster wasn't the only engineering challenge the team faced. If you've ever stepped inside a server room, or, like me, foolishly installed one in your own basement, you know that fan cooling can be loud. The museum team used passive convection cooling via a steel rack chassis and aluminum tray mounts for each Mac Mini. Compared to the roaring thunder of a modern data center, this cluster is nearly inaudible.
Macs are mounted vertically on aluminum racks in a steel chassis. Credit: Museo de Historia de la Computación
The secret to the near-silence comes from vertical mounting. The PCs' vertical orientation, combined with the steel chassis and aluminum trays, allows the tower to act as a natural thermal chimney. Hot air rises through the structure and out of the top grills without the need for added mechanical fans. According to the museum, the only noticeable noise inside the Cray-1 replica comes from two gigabit Ethernet switches at the base of the unit that register between 30–33 decibels, though the team plans to replace them with silent models. The fully assembled replica is said to make so little audible sound that you have to get right up next to the tower to be able to hear anything. While exact dB measurements from inside the exhibit weren't available, each individual PC is stated to produce 12–15 dBA of noise at idle.
Mission control
To manage this quiet giant, designers built a custom terminal that looks straight out of a Cold War control room. The team combined elements of the DEC VT05 and Processor Technology Sol-20 Terminal Computer designs of the 1970s, even incorporating an analog control panel, with future plans to add original lamps from an IBM System/3. One master Mac Mini resides in the terminal and serves to direct all the other cluster nodes.
Classic design elements lend the Cray-1 control terminal some retro style. Credit: Museo de Historia de la Computación
The original design had planned for the terminal to feature CRT monitors for added authenticity, but modern flat Samsung displays eliminated the connectivity headaches that come from attempting to bridge different technological eras. Future design plans will see 3.5- and 5.25-inch floppy drives mounted to the underside of the desk, and a 3D-printed shell will encase the keyboard to mimic the look of the classic HP 250 design.
Mockup of the shell that will fit over the existing PowerMac G4 keyboard. Credit: Museo de Historia de la Computación
Targeting the TOP500
The Cray-1 team hopes to fill the currently empty second half of the tower through a crowdfunding campaign to secure 70–80 additional M4 Mac Minis. The goal: create a cluster capable of ranking on the TOP500 supercomputers list.
The Cray-1 replica among its classic computing peers. Credit: Museo de Historia de la Computación
The replica is on permanent display in the museum, alongside two unused authentic Cray CX1 systems. The Museo de Historia de la Computación offers guided tours on Saturdays from 11:30 am to 2 pm. Additional project information can be found on the museum website.
 Log in


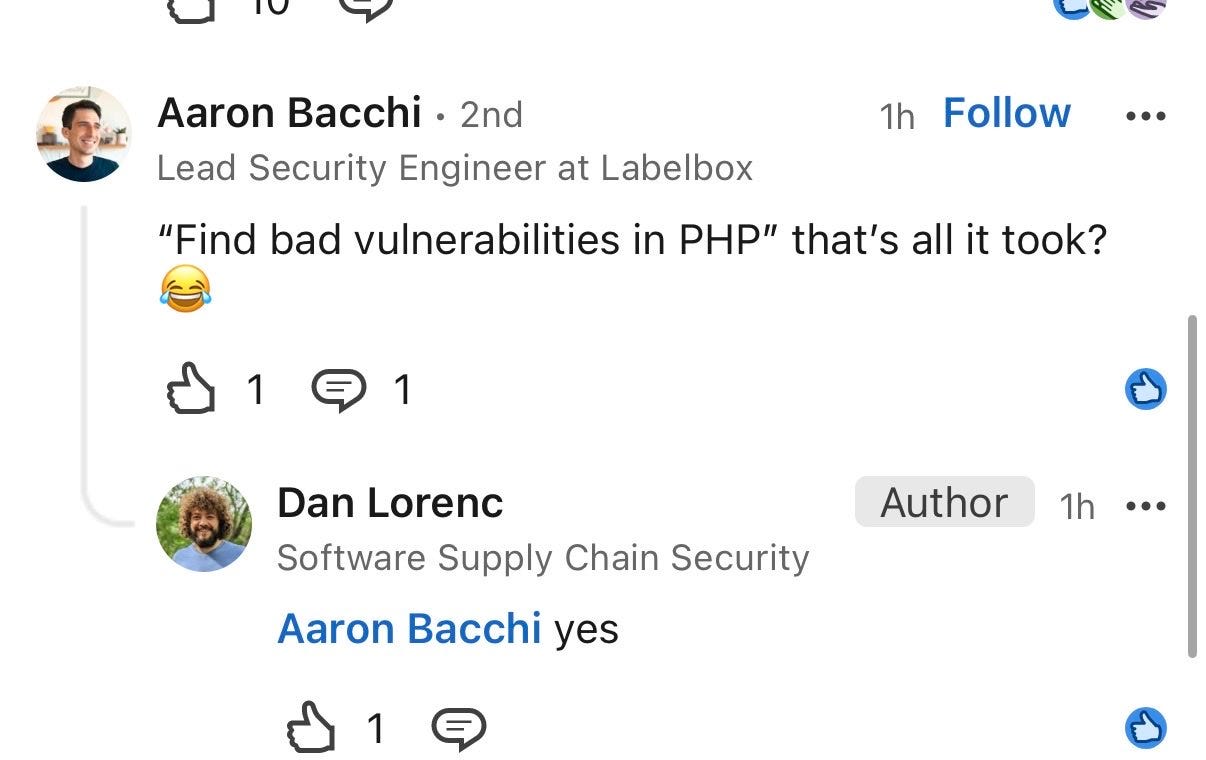
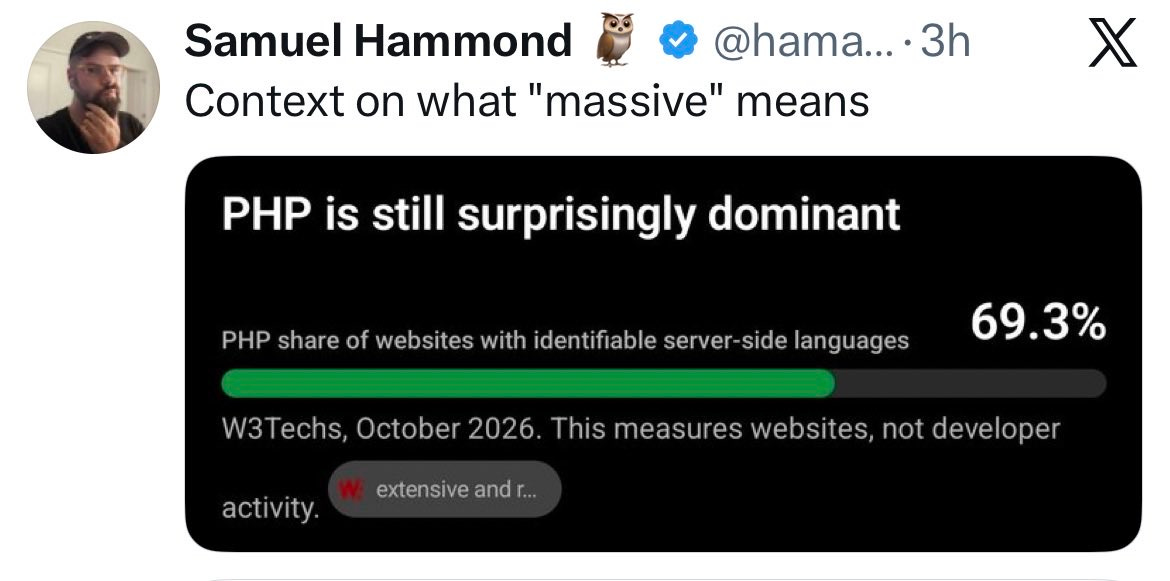
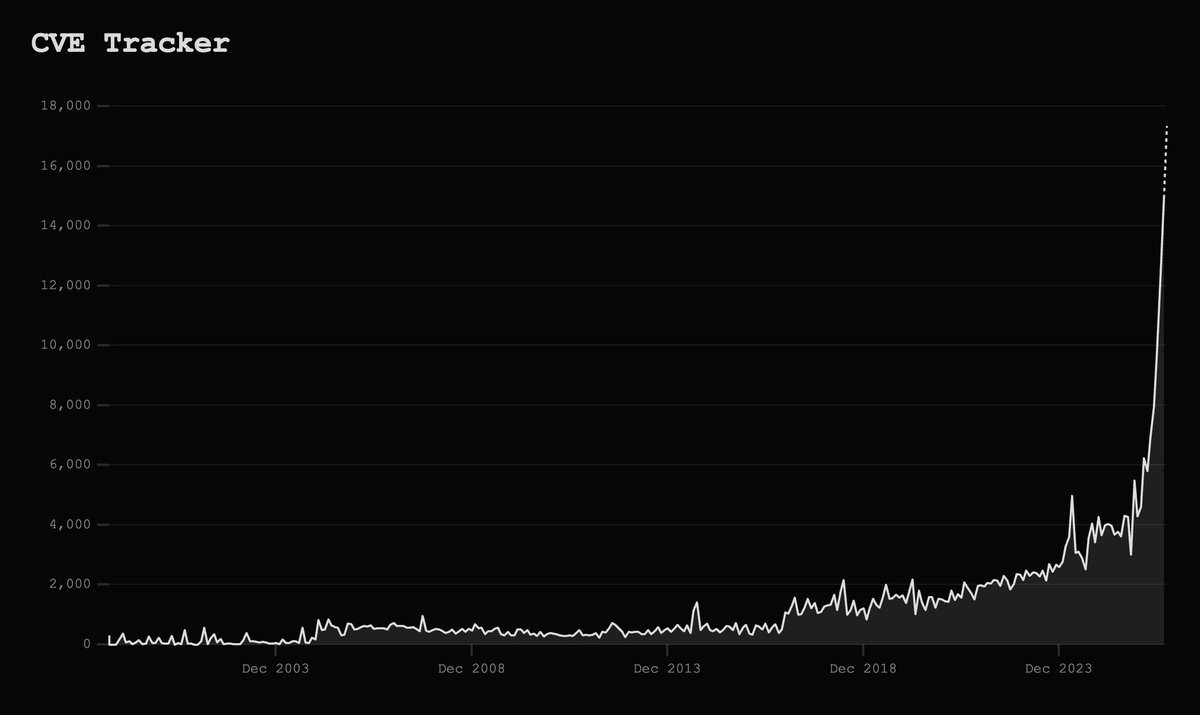

PHP UPDATE: 4chan has gone read-only and Something Awful has shut its forums as American sites brace for the PHP patch. 4chan says it is “temporarily read-only while we await an urgent PHP security update.” Something Awful says the flaw “allows for the kind of hacking you see in movies (but in real life).” Bookmarking service Pinboard, game publisher Choice of Games, history site Damn Interesting and the explain xkcd wiki are offline too, as is art site Fur Affinity. DeviantArt is also down “for maintenance” but has not said why. PHP’s fix is due at 14:00 UTC, 10am in New York. Huzaifa: 4chan going read only by choice is how you know it’s serious.
e: ICYMI: Today was basically the worse day of the year for cyber security incidents
CRITICAL: GitLab flaw (CVSS 10.0) affects 12 years of releases. CVE-2026-110264 could allow unauthenticated remote code execution on self-managed servers. The Hacker News: GitLab released fixes on October 21 for a flaw that lets an attacker run code on a self-managed server without logging in, and it affects every version of the software going back to 7.0, released in 2014. The fix matters even for administrators who patched nine days earlier: the October 12 update covered only versions 19.2 and later, and the new fixed versions sit one patch above it, so an instance updated then is in range again.
If you’re reading this website, you probably know more than most of the people in your life about what’s happening! they’re not talking about any of this stuff on the news, it’s too arcane and weird and sudden. It is on us. Good time to call or text your family and friends, have some cash on hand, have a meetup point in your neighborhood for if the Internet goes down entirely, etc. The full prepper mode for shit hitting the fan is probably something like what Andreas posted here but you can get 80% of the way with 20% of the effort. Think about what that would mean for you in your situation, and the people you care about, and talk to them about it sooner than later. And as always, the most important part of prepping is having a strong support network and caring for each other. “Going off grid” isn’t the move, it just makes you isolated and you have to do everything yourself. We are social animals. Community is our superpower







 The Cray-1 replica, complete with iconic padded bench seating. The only thing missing is Robert Redford and Ben Kingsley having a discussion on SECTEC Astronomy. Credit: Museo de Historia de la Computación
Credit:
Museo de Historia de la Computación
 Macs are mounted vertically on aluminum racks in a steel chassis. Credit: Museo de Historia de la Computación
 Classic design elements lend the Cray-1 control terminal some retro style. Credit: Museo de Historia de la Computación
 Mockup of the shell that will fit over the existing PowerMac G4 keyboard. Credit: Museo de Historia de la Computación
 The Cray-1 replica among its classic computing peers. Credit: Museo de Historia de la Computación